INSIGHTS | October 23, 2026

Below the Threshold: Why Britain’s Smallest Power Generators Face a Four-Year Cyber Security Gap

Key Takeaways

  • A small-scale gas generator was taken offline for four days in July 2026. The UK Government confirmed the incident but has not formally attributed it. [1]
  • Under the Network and Information Systems Regulations 2018, electricity generation is captured only at 2GW cumulative capacity, and the threshold expressly excludes generators that are not connected to a transmission system. [2]
  • On 5 August 2026 the Department for Energy Security and Net Zero and Ofgem confirmed that baseline cyber resilience requirements for all Ofgem licensees will be built on Cyber Essentials Plus, consulted on during 2027 and in place across the sector by the end of 2030. [3]
  • The same government response acknowledges that Cyber Essentials Plus excludes operational technology and lacks controls covering governance, incident response, risk management and supply chain. Its Plus tier applies the same five technical controls as Cyber Essentials with independent testing, rather than extending them. [3] [9]
  • IT and OT segregation was the single most requested additional control among consultation respondents, raised by 18 of the 49 organisations and individuals who replied. [3]

Why This Matters Now

In July 2026 a small-scale British generating asset stopped producing power for four days following a cyber incident. Michael Shanks, Minister of State at the Department for Energy Security and Net Zero, confirmed that the incident had affected a small-scale energy generator, and the Department stated that at no point was the wider energy system at risk. [1] Press reporting linked the intrusion to Iranian-aligned actors, though the UK Government has made no formal attribution.

The detail that matters for security leaders is not the attribution. It is the position of the asset. A four-day outage at a small distribution-connected generator is an outage at something well below the regulatory perimeter drawn in 2018, which means the operator was almost certainly under no statutory cyber resilience obligation at all.

That perimeter is not a historical accident. The Government’s own Energy Sector Cyber Security Strategy states that the NIS Regulations were only ever intended to apply to the most critical operators and therefore do not provide holistic coverage of the energy system. [4] The strategy also commits Government to encourage more reporting of cyber incidents that fall below NIS thresholds, which is a plain acknowledgement that the sub-threshold estate is a blind spot.

The threat is not theoretical. In December 2025 a threat actor targeted around 30 distributed renewable assets in Poland, including wind and solar farms and a combined heat and power plant. Generation and heat supply held, and the plant involved served nearly 500,000 heat customers. What matters is how the attacker got in: internet-exposed firewall appliances without multi-factor authentication, unpatched devices and reused credentials. Most of those routes could have been closed by basic cyber hygiene. A parallel attack the same day on a smaller plant serving 50,000 residents did interrupt cogeneration, shutting down a steam turbine and the water treatment system. [5] [6]

Meanwhile the estate is growing. Government projections cited in the March 2026 consultation put battery storage capacity on a six-fold increase and wind and solar capacity almost tripling by 2030. [5] Ofgem currently regulates just over 1,400 licensed operators, and Government has described the absence of cyber resilience requirements across a large proportion of them as one of two fundamental reform needs. [3]

What the Regulatory Position Actually Is

Schedule 2 of the NIS Regulations 2018 sets the thresholds at which an operator becomes an Operator of Essential Services. For downstream gas and electricity these are as follows.

Essential ServiceElectricityGas (Downstream)
Generation2GW or more (cumulative)N/A
TransmissionMore than 250,000 final customersMore than 250,000 final customers
Offshore Transmission2GW or more (cumulative)N/A
DistributionMore than 250,000 final customersMore than 250,000 final customers
Interconnectors1GW or moreMore than 20M m3 gas per day
SupplyMore than 250,000 final customersMore than 250,000 final customers
Load Control300MW or moreN/A

Source: DESNZ and Ofgem consultation documents, drawn from NIS Regulations 2018 Schedule 2. Generation excludes nuclear generators and generators not connected to a transmission system. Capacity is cumulated across affiliated undertakings. Load control is not yet in force and will be commenced through the Cyber Security and Resilience Bill. [2] [3]

Two features of that table deserve attention. First, generation capacity is cumulated across a corporate group, so a modest site inside a large portfolio can sit above the line while a standalone site of identical rating sits below it. Second, generators not connected to a transmission system are carved out regardless of size, which removes most distribution-connected embedded generation from scope entirely.

Government consulted on this between 27 March and 22 May 2026 and published its response on 5 August 2026. Nineteen respondents told Government that the electricity generation threshold should change. Twenty-one argued that thresholds should be driven by risk or impact rather than by supply or generation volume, and 19 said the sector has become distributed to the point where current thresholds no longer reflect where risk arises. Six respondents proposed specific replacement figures, including 200MW and 500MW for generation. [3]

Government has not adopted a new number. It has commissioned the National Energy System Operator to advise on which services and thresholds should apply, and intends to consult on any revisions during 2027, subject to the Cyber Security and Resilience Bill receiving Royal Assent. The response states that Royal Assent is expected in early 2027, though secondary coverage consistently reports an expectation of late 2026. The Bill completed Lords Second Reading on 14 July 2026 and entered Lords Committee Stage on 1 September 2026. [3] [8]

Alongside that review, Government confirmed it will introduce baseline cyber resilience requirements for all Ofgem licensees, delivered through licence conditions and founded on Cyber Essentials Plus. Ofgem will consult on the detail during 2027. The public commitment is that a baseline level of cyber resilience will be in place across the whole downstream gas and electricity system by the end of 2030. Any intermediate tier between baseline and NIS is expected to be considered only after 2030. [3]

Who is Affected by the Sub-Threshold Gap?

Sub-threshold generators and distributed energy operators. Operators of embedded gas plant, solar, onshore wind, battery storage and long duration storage that fall below 2GW, or that are not transmission-connected, carry no statutory cyber resilience obligation today and will carry none until baseline requirements are implemented through licence conditions. Many of these sites are unmanned and dependent on remote access.

NIS-designated operators. Designation does not insulate a large operator from the gap. NIS requirements apply only to the network and information systems on which the essential service relies, which Government acknowledges leaves ancillary, supporting and back-end systems outside scope. [5] Large operators also depend on smaller counterparties for flexibility, balancing and aggregation.

Aggregators, flexibility platforms and remote service providers. Consultation respondents identified flexibility services, aggregators and orchestration platforms as the most commonly proposed additions to the essential services list, alongside digital and data platforms and remote monitoring and management providers. [3] Some of these organisations will be captured as large load controllers at 300MW of aggregate controllable load. Many will not.

Boards and investors in generation assets. The regulatory floor is now dated and public. A board that waits for 2030 is accepting four years of exposure on an asset class that has already been taken offline once.

What Are the Challenges the 2030 Baseline Does Not Solve?

The most significant issue is that the announced remedy is shaped for information technology, not for the control systems that took the plant offline.

Government has been candid about this. The consultation observed that Cyber Essentials is primarily suitable for IT, that many downstream gas and electricity operators rely on SCADA systems, programmable logic controllers, human machine interfaces and remote telemetry units, and that applying Cyber Essentials controls to those environments can be challenging and in certain circumstances unsuitable. [5] The government response goes further, recognising that Cyber Essentials Plus has limitations for the energy sector in relation to the exclusion of operational technology and the absence of controls for governance, incident response, risk management and supply chain. [3]

Respondents said the same thing with numbers behind it. IT and OT integration or network segmentation was the leading requested addition at 18 respondents, followed by incident response and exercising at 17, remote access management at 13, supply chain visibility at 12 and governance at 10. When asked for alternative frameworks, respondents most often named the NCSC Cyber Assessment Framework at 16 and IEC 62443 at 15, ahead of ISO 27001 at 14. [3] The sector asked for an OT-aware standard. What has been confirmed so far is an IT scheme that Government intends to build on, with the additional controls still to be designed. It is worth being precise about what the Plus tier adds: Cyber Essentials Plus applies the same five technical controls as Cyber Essentials and subjects them to independent technical testing rather than extending them. [9] Choosing Plus over the base scheme raises the assurance level, not the scope.

Three further constraints compound this. Government intends that, where possible, baseline requirements should apply only to systems not already covered by existing cyber resilience obligations, which creates scope boundaries that operators will need to evidence rather than assume. [3] Consultation respondents reported that the prescriptiveness of Cyber Essentials controls and the inability to use compensating controls were common drivers of cost in OT-heavy and legacy environments. [3] And the assurance route for complex estates is still under exploration, with Government committing only to examine the potential of NCSC Cyber Essentials Pathways. [3]

The practical conclusion for a security leader is that compliance and resilience are not the same programme here, and neither of them arrives before 2030.

How IOActive Can Help

The gap this post describes is not a compliance problem yet, which is precisely why it is an assessment problem now. An operator below the 2GW line has no licence condition to evidence against and no NIS designation to scope, so the only reliable way to establish its position is to test the estate against a framework the eventual baseline will have to catch up to.

IOActive has operated in industrial control environments since building the first proof-of-concept worm against the smart grid in 2009 [10], and has helped define standards and best practices including NIST 800-53 and 800-37. The services below map to the specific gaps the 2030 baseline leaves open.

Full Stack Security Assessments

Government has confirmed that Cyber Essentials Plus excludes operational technology and that applying its controls to SCADA systems, programmable logic controllers, human machine interfaces and remote telemetry units can be unsuitable. Our Full Stack assessments examine the whole environment rather than a single layer, covering the controllers and HMIs at distribution-connected sites, the OT/IT boundary, and the cellular and vendor paths that commonly provide unmanned generation assets with connectivity nobody has inventoried. Where the baseline will eventually ask for evidence, an assessment produces it rather than assuming it.

Hardware and Firmware Security Research

The assets in question are largely unmanned and remotely operated, which places the security of the controller and telemetry unit itself in scope rather than only the network around it. Our hardware and firmware research examines the devices deployed at these sites directly, at a depth that network-layer testing cannot reach and that no IT-derived certification scheme currently asks for.

Supply Chain Integrity

Consultation respondents named supply chain visibility among the leading controls missing from Cyber Essentials Plus, and identified aggregators, flexibility platforms and remote monitoring providers as the additions most often proposed to the essential services list. Our Supply Chain Integrity work assesses the posture of technology providers and critical third parties, covering firmware, embedded systems, remote access arrangements and procurement, so that inherited risk is identified before it becomes a shared incident. For operators contracting with aggregators and remote service providers, this is the exposure that sits outside their own perimeter and inside their own outage.

Red Team and Purple Team Services

Incident response and exercising was the second most requested addition to the baseline, at 17 respondents. Adversary simulation is how an operator establishes whether an intrusion at a small asset would be detected and contained before it interrupts generation, rather than assuming the segmentation on the network diagram holds under test.

Advisory Services

The 2027 consultations will ask operators to state which systems fall inside a future baseline, which already sit inside NIS scope, and where residual OT exposure lies. That is a scoping determination an operator has to be able to defend, not describe. Our Advisory Services cover programmatic security review, security programme development and management, and Virtual CISO support, and the output is a documented scope position for each asset, a remediation sequence with named owners and dates, and the evidence pack a board or regulator will ask for.

If you would like to discuss where your generation or distributed energy assets sit against the thresholds described in this post, and what the residual OT exposure looks like, we welcome the conversation.

  1. Establish the regulatory position of every generating asset in the portfolio, including cumulative group capacity and whether the connection is to a transmission or a distribution system, and record the basis for each determination.
  2. Treat the 2030 baseline as a floor rather than a target, and assess the estate against an OT-aware framework such as IEC 62443 or the NCSC Cyber Assessment Framework rather than waiting for licence conditions to be drafted.
  3. Inventory remote access into unmanned sites, including vendor and maintenance pathways, and verify that segmentation between corporate IT and control networks holds under test rather than on the network diagram.
  4. Extend incident response plans to cover loss of generation at a sub-threshold asset, and exercise them, given that incident response and exercising was the second most requested control in the consultation.
  5. Review contractual cyber security obligations with aggregators, flexibility platforms and remote monitoring providers, several of which may be brought into NIS scope during the 2027 review.
  6. Engage with the Ofgem consultation expected during 2027, since the additional controls that sit above Cyber Essentials Plus are still being designed and sector evidence will shape them.

Conclusion

The regulatory perimeter for British electricity generation was drawn around a small number of very large assets in 2018, for an energy system that no longer exists. Government has recognised this, commissioned advice on where the line should move, and committed to a baseline for every Ofgem licensee by the end of 2030. That work is welcome and it is also four years away, and the scheme chosen as its foundation does not currently reach operational technology.

Operators that have already been targeted do not have four years, and press analysis published a month after the incident concluded that Britain’s small power plants face continued cyber risk. [7] The organisations that come through the next phase in good order will be those that treat the 2030 baseline as the minimum they will eventually be asked to evidence, and build OT security ahead of it on their own timetable.

References

  1. The Register, “Iran-linked cyberattack shut down a UK power plant”, 24 August 2026, carrying the Department for Energy Security and Net Zero statement on the small-scale energy generator incident. https://www.theregister.com/security/2026/08/24/iran-linked-cyberattack-shut-down-a-uk-power-plant/ First reported by The Sunday Telegraph, 22 August 2026 (paywalled).
  2. The Network and Information Systems Regulations 2018, Schedule 2, U.K. Essential Services and Threshold Requirements. https://www.legislation.gov.uk/uksi/2018/506/schedule/2 (revised text as in force at 2 September 2026).
  3. Department for Energy Security and Net Zero and Ofgem, “Reshaping cyber regulation in downstream gas and electricity: government response”, 5 August 2026. https://www.gov.uk/government/consultations/whole-energy-cyber-resilience-requirements-reshaping-cyber-regulation-in-downstream-gas-and-electricity
  4. Department for Energy Security and Net Zero, Ofgem, NCSC and NESO, “Energy Sector Cyber Security Strategy”, 28 May 2026. https://www.gov.uk/government/publications/energy-sector-cyber-security-strategy/energy-sector-cyber-security-strategy
  5. Department for Energy Security and Net Zero and Ofgem, “Reshaping cyber regulation in downstream gas and electricity: consultation document”, 27 March 2026. https://assets.publishing.service.gov.uk/media/69c51142471d520038d0f68d/whole-energy-resilience-consultation-document.pdf
  6. CERT Polska, “Energy Sector Incident Report – 29 December”, published January 2026. https://cert.pl/en/posts/2026/01/incident-report-energy-sector-2025/ (full report: https://cert.pl/uploads/docs/CERT_Polska_Energy_Sector_Incident_Report_2025.pdf). See also CERT Polska, “Follow-Up Report of the December 2025 Energy Sector Incident”, August 2026. https://cert.pl/en/posts/2026/08/incident-follow-up-report-energy-sector-2025/
  7. The Guardian, “UK’s small power plants face continued cyber risk after Iran-linked hack”, 27 August 2026. https://www.theguardian.com/business/2026/aug/27/uk-small-power-plants-risk-cyber-attacks-iran-hack
  8. Cyber Security and Resilience (Network and Information Systems) Bill, HL Bill 32, introduced to Parliament 12 November 2025. Lords Second Reading 14 July 2026, Lords Committee Stage from 1 September 2026. https://bills.parliament.uk/bills/4035
  9. National Cyber Security Centre, Cyber Essentials. https://www.ncsc.gov.uk/cyberessentials/overview
  10. M. Davis, IOActive, “Advanced Metering Infrastructure (Smart Grid) Device Security”, Black Hat USA 2009. https://blackhat.com/presentations/bh-usa-09/MDAVIS/BHUSA09-Davis-AMI-SLIDES.pdf
INSIGHTS | October 20, 2026

Cyber Risk Management Strategies for Enterprises

Cybersecurity war room.

“The most effective cyber risk management strategies prioritize business impact alongside technical risk.” – IOActive Security Team

The strongest cyber risk management strategies begin with a business question. Which failures could stop a critical business service, harm people, cut revenue, or damage trust? A list of flaws cannot answer that question. Leaders need to see how weaknesses combine, which services they threaten, and what action will cut the risk.

This framework focuses on five decisions:

  1. Link technical risk to business impact.
  2. Test real attack paths through offensive security assessments.
  3. Treat third parties and Operational Technology (OT) as business dependencies.
  4. Set risk rules for each AI use case.
  5. Make continuous validation part of governance.

Use this framework during annual planning, major technology changes, supplier reviews, and new AI approvals. It gives executives a shared way to rank risk. It provides technical teams with a testable set of assumptions and service owners with a clear role. The result is a shorter path from a security finding to a funded business decision. It also helps separate risks that need immediate action from risks that can be tracked.

Start With Business Impact, Not a Finding Count

The NIST Cybersecurity Framework (CSF) 2.0 organizes security work into six functions: Govern, Identify, Protect, Detect, Respond, and Recover. Together, these functions help a company set priorities, reduce risk, spot failures, respond to incidents, and restore key services. They become most useful when the organization applies them to the services it must keep running.

Start with the services the business must protect. A factory may depend on production uptime, safe machine control, maintenance access, and a safe stop. A bank may depend on payments, administrative access, market links, and customer login. The same flaw can demand a different response based on its place in that service chain.

Business Impact Risk Prioritization Matrix

Decision factorLowMediumHigh
Business impactLocal inconvenienceService degradationSafety, revenue, or regulated-service interruption
Attack pathRare conditions requiredSeveral prerequisitesDirect or demonstrated path
Control confidenceTested and reliablePartly validatedUnknown, bypassed, or contradicted by evidence
Dependency exposureIsolated assetShared serviceSingle point of failure
Time to consequenceWeeks or monthsDaysHours or less
Executive actionTrack and reviewFund targeted reductionEscalate, assign an owner, and set a deadline

Use the matrix to direct resources toward paths that could interrupt a critical business service. A demonstrated path to that service deserves faster action than an isolated flaw on a test system.

Test the Risk Model Through Offensive Security Assessments

A risk model contains assumptions. It assumes that a control will block an attack, a team will spot it, and a restore process will work under pressure. An offensive security assessment tests those assumptions. It checks whether an attacker can connect separate weaknesses into a path to a critical business service.

A flaw scan may find an exposed system, but it does not show what an attacker can do with that access. An offensive assessment goes further: Which account or network boundary does the access bypass? What can the attacker reach? Could the result affect the business?

This distinction also clarifies the roles of Red Team and Purple Team engagements. Red Team work simulates adversary behavior, while Purple Team work brings offensive and defensive teams together to test controls, improve detection, and close response gaps.

A well-scoped assessment should answer four questions:

  1. Can an intruder reach a critical business service? Map the route from first access to the service. Look for account escalation, weak network limits, admin rights, exposed admin tools, and third-party access.
  2. Which controls should stop or flag the path? Name each expected prevention and detection point. Then name its owner and the proof that it worked.
  3. How quickly would the company know? Compare alert and triage time with the time an attacker would need to cause harm. Look for blind spots and unclear response paths.
  4. What action would limit harm? Define the contain, restore, or safe-stop action that protects the service under attack conditions.

IOActive’s research covers embedded devices, industrial control systems, aviation systems, vehicles, hardware, and connected products. That research can expose gaps where software, hardware, physical access, and safety meet.

Treat Third Parties and Operational Technology (OT) as Business Dependencies

Third-party risk should not stop at a questionnaire or contract clause. Cloud platforms, managed service firms, software suppliers, industrial integrators, and logistics partners may hold access, support a critical business service, or affect restoration if the company cannot replace them quickly.

For each third-party dependency, document what the party can see, change, or stop. Then assess its access path, data exposure, restore role, single points of failure, and exit options. The 2025 Verizon Data Breach Investigations Report found that third parties were involved in 30% of the breaches analyzed. That was twice the prior year’s share.

Operational technology (OT) needs the same business lens, with extra attention to safety, uptime, physical processes, and change control. Review asset lists and network separation with operators and engineers, not only with IT staff. CISA links accurate OT asset knowledge with security, maintenance, and uptime. CISA and its partners also recommend limiting OT access to what each user needs.

Third-Party and OT Evidence Matrix

DependencyEvidence to requestDecision it should support
Cloud or SaaS providerRecovery evidence, access review, and logging coverageWhether the service can support a critical process
Managed service providerPrivilege map, access approvals, and logging testWhether provider access is limited and observable
Software supplierUpdate checks and vulnerability handlingWhether updates create unacceptable exposure
Industrial integratorOT attack-path review and remote-access controlsWhether maintenance access could affect safe operations
Logistics partnerAlternate-process test and dependency mapWhether the business can continue during supplier failure

Use the evidence to set a fix, name the risk owner, and test the restore plan where needed.

Govern AI Adoption by Use Case

AI is not a single risk category. A public chatbot, coding assistant, customer-facing model, and plant-support application have different users, data, permissions, failure modes, and business impact. Treating them as one program can hide the controls each use case needs.

NIST’s AI Risk Management Framework supports managing AI risks during development and use. Before approval, the owner should state the purpose, users, and data access. The owner should also define decision power, likely misuse, human checks, logs, and a rollback plan. IOActive’s AI security services describe support from concept through deployment. That lifecycle view helps teams test risk during buying, data preparation, model use, integrations, and live operations.

AI Use-Case Risk Gate

AI gateEvidence to requestApproval question
PurposeBusiness outcome and affected usersIs the use case necessary and bounded?
DataPermissions, retention, and sensitive contentCan the system access only needed data?
BehaviorAbuse cases, output tests, and failure modesWhat could it produce or recommend incorrectly?
AuthorityActions the system can recommend or initiateWhich actions require human approval?
ResilienceMonitoring, rollback, and incident playbookHow will the team stop or restore it?

Approved systems still need checks after launch. A change in the model, data, integration, user group, or authority can change the risk.

Make Continuous Validation Part of Cyber Risk Management Strategies

A risk plan loses value when its proof becomes old. Systems change. Third parties gain access. Cloud accounts grow. AI goes live. New research changes a threat model. A control that worked during a test may not protect the same critical business service after a design or process change.

Continuous checks do not mean scanning every system at all times. They mean checking the controls that protect critical business services. NIST CSF 2.0 treats security risk management as an ongoing practice. It includes continuous monitoring within the Detect function.

Continuous Validation Trigger Matrix

TriggerValidation actionOwner or participant
Major design changeUpdate attack paths and control assumptionsSecurity architecture and service owner
New third-party accessReview privileges, logs, and restore dependencyVendor owner and security
AI system enters productionTest abuse cases, permissions, logs, and rollbackAI owner, privacy, and security
OT process or firmware changeReview safety limits, network separation, and remote accessEngineering, operations, and security
Completed fixRetest the original attack path and remaining accessControl owner and assessor

For board and executive reports, track the share of critical business services with tested attack paths and overdue high-priority fixes. Also track time to detect and contain a tested path and the share of restore exercises that meet their goals.

Put Cyber Risk Management Strategies Into Practice

The most effective cyber risk management strategies connect technical evidence to business consequences. IOActive combines threat research, adversarial testing, and security advice to help organizations test the assumptions behind their plans.

Sources

INSIGHTS | October 16, 2026

Signal Messenger Security: A Research Case Study

SetWindowDisplayAffinity code on signal to receive no display error.

Signal Messenger is widely recognized for protecting private communications, but secure messaging depends on controls beyond encryption. This Signal Messenger security case study examines how IOActive tested Signal Desktop’s Windows screen-capture protection and what the results reveal about evaluating application controls against realistic attacker capabilities.

Signal Messenger Security: At a glance

Problem
Signal Desktop’s Windows content-protection feature prevents the application window from appearing in screenshots and screen recordings. However, the control relies on the assumption that only Signal’s own process will change the window’s display-affinity setting.
Solution
IOActive traced the feature from Signal’s open-source code through Electron and the Windows graphics stack, then tested whether the protection could be removed from outside the application. The team also analyzed the Windows ownership check that enforced the control.
Results
Direct calls from another process failed, including calls from an administrator process. IOActive successfully removed the protection by executing the relevant API call within Signal’s process using CreateRemoteThread, demonstrating that local code execution can undermine this type of defense-in-depth control.

“Security controls should be tested against the conditions attackers can create, not only the conditions they were designed to handle.”

The security control under review

The investigation began when IOActive Senior Security Consultant Taha Draidia noticed that Signal Desktop was missing from a screen-sharing session. Signal Desktop is built with Electron, and its publicly available source code exposed the relevant contentProtection setting. A search of the code identified the call to window.setContentProtection(contentProtection), which enables or disables the feature.

According to the Electron BrowserWindow documentation, enabling content protection on Windows maps to the Windows API SetWindowDisplayAffinity, using the WDA_EXCLUDEFROMCAPTURE flag. On supported Windows versions, this excludes the application window from screen captures. On older versions, the behavior falls back to displaying a black rectangle.

The control is implemented below the application interface, in the Windows desktop and graphics stack. That makes it more difficult to defeat through ordinary application settings, but it does not make the control independent of the endpoint’s security state.

How IOActive tested the protection

The research team first identified Signal’s top-level window and obtained its window handle. The Windows APIs EnumWindows, GetWindowTextW, and GetWindowThreadProcessId can be combined to locate a window by its title and associated process.

The relevant function accepts a window handle and an affinity value:

  • WDA_NONE, which removes the capture restriction
  • WDA_MONITOR, which limits content to a monitor
  • WDA_EXCLUDEFROMCAPTURE, which excludes the window from capture

IOActive evaluated three ways to remove the restriction.

Research phaseMethod testedResultSecurity lesson
1Call SetWindowDisplayAffinity(hwnd, WDA_NONE) from another processRejected with ERROR_ACCESS_DENIEDA valid window handle does not automatically grant permission to change every property associated with that window.
2Repeat the call from an elevated administrator processRejected with the same errorThe control is based on process ownership, not simply administrator privilege.
3Execute the API call within Signal’s process using CreateRemoteThreadSuccessfulLegitimate APIs can be combined with process injection to satisfy an ownership check that blocks cross-process calls.

Sources for the table: IOActive’s original research, Microsoft’s SetWindowDisplayAffinity documentation, and Microsoft’s CreateRemoteThread documentation.

Why the first attempts failed

The first attempt was straightforward: identify Signal’s window and call SetWindowDisplayAffinity from a separate process. Windows rejected the request with ERROR_ACCESS_DENIED.

IOActive repeated the test from a process running with administrator privileges. The result did not change. Elevation was not enough because the check was not primarily evaluating whether the caller was an administrator. It was evaluating whether the caller belonged to the process that owned the target window.

The test exposed an important assumption behind the control.  A security control may correctly enforce its documented API contract while still depending on a broader assumption about the endpoint. In this case, the control expected the API call to originate from Signal’s own process. It did not establish a stronger boundary against an attacker who could execute code in that process.

The successful bypass

The third approach used CreateRemoteThread to execute the display-affinity call inside Signal’s process context. The proof of concept is available in our public GitHub repository.

Because the call originated within Signal’s process, the process-ownership check was satisfied. The protection was then removed without requiring the API call to come from an administrator process.

This result does not mean Signal’s end-to-end encryption was broken. The research evaluated a Windows desktop presentation control, not Signal Messenger’s cryptographic design. The finding demonstrates that screen-capture protection is a defense-in-depth measure whose effectiveness depends on the integrity of the local endpoint.

Confirming the assumption through kernel analysis

IOActive did not stop after demonstrating the behavior. The team reverse-engineered the Windows implementation to understand why the first two approaches failed.

The user-mode call chain leads from user32!SetWindowDisplayAffinity to the NtUserSetWindowDisplayAffinity system call. The ownership enforcement occurs deeper in the Windows graphics subsystem. The kernel compares the process associated with the target window against the process associated with the calling thread. If those values differ, Windows returns ERROR_ACCESS_DENIED.

A remote thread changes that condition by causing the API call to execute inside the target process. The bypass does not defeat the ownership comparison directly. It satisfies the comparison by moving execution into the process that owns the window.

IOActive also examined research into the Desktop Window Manager, including the DWMShield proof of concept, which reaches the internal graphics routine responsible for applying the capture-exclusion state. Together, these paths illustrate that a control enforced in the graphics stack can still be affected by code execution elsewhere in the operating system.

What this case study means for product security

This Signal Messenger security investigation offers several lessons for software and product teams:

First, application security controls should be evaluated against the actions available to a local attacker, not only ordinary user behavior. If an attacker can execute code within a trusted process, controls that rely on process identity may no longer provide the intended protection.

Second, API-level correctness is not the same as system-level resilience. SetWindowDisplayAffinity correctly rejects unauthorized cross-process calls. The weakness lies in combining that control with another legitimate capability: process injection.

Third, security testing should follow a control through its complete implementation path. IOActive combined source-code review, API analysis, Windows internals research, reverse engineering, and offensive testing. That combination exposed an assumption that would have been difficult to identify through surface-level functional testing alone.

Finally, screen-capture protection should be treated as one layer in a larger endpoint security strategy. It can reduce casual or routine capture, but it cannot replace endpoint protection, application hardening, monitoring, and defenses against local code execution.

Signal Messenger Security: Major takeaways

IOActive’s research into Signal Desktop shows why product security requires more than verifying that a security setting works under normal conditions. The screen-capture control performed as designed against ordinary capture attempts and rejected direct calls from standard and elevated external processes. However, deeper testing showed that code executing within Signal’s own process could remove the restriction.

The case study positions Signal Messenger security within a broader engineering principle: security controls must be tested against the conditions an attacker can create. IOActive’s work across application security, reverse engineering, Windows internals, and offensive testing shows how research-led testing can reveal the difference between a control that works as documented and a control that remains effective under realistic attack conditions. It also demonstrates how IOActive goes above and beyond to find the root cause of important cybersecurity threats, with a research-led workflow that makes them one-of-a-kind in the industry.

Need to evaluate your own application security controls against realistic attacker capabilities? Contact IOActive to discuss Signal Messenger security, product security research, and advanced offensive testing.

INSIGHTS | October 13, 2026

From 30 Systems to Over 100: What CISA’s Revised Water Sector Figures Reveal About the OT Detection Gap

Key Takeaways

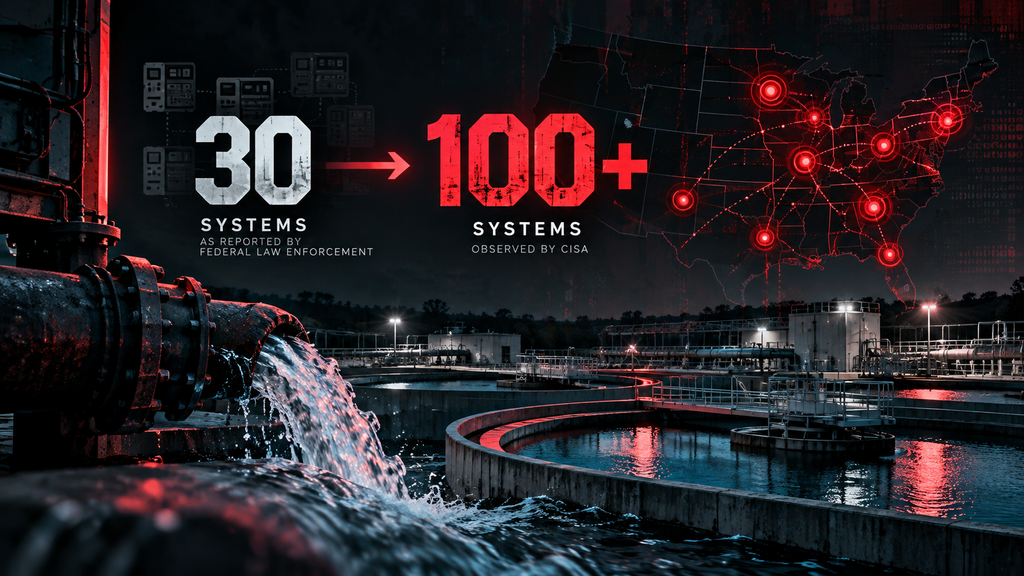
  • CISA has revised the scale of the July 2026 water sector campaign from the roughly 30 systems described by federal law enforcement at the time to more than 100 internet-exposed systems across at least 12 US states [1] [3].
  • The revised figure originated with CISA’s own observation, published on 21 August 2026 in exposure reduction guidance, rather than with incident reports submitted by the affected utilities [1] [3].
  • CISA has warned that the cellular modems involved may have been installed by operators, vendors or system integrators, and may not be documented or included in routine attack surface scans [4].
  • The UK position is structurally similar. The Drinking Water Inspectorate received five cyber incident reports from water suppliers between January 2024 and October 2025, all concerning systems outside NIS scope and all submitted voluntarily rather than under a legal duty [5].
  • Reporting obligations under the UK NIS Regulations, the Cyber Security and Resilience Bill and EU NIS2 are all triggered by the operator becoming aware of an incident. Lowering a reporting threshold does not close a detection gap.

Why Do the Revised Figures Matter Now?

Malicious activity against US water and wastewater systems began on 26 July 2026 [2]. In the weeks that followed, federal law enforcement described a campaign affecting approximately 30 water systems in Minnesota and a small number of other states [2].

On 21 August 2026, CISA published internet exposure reduction guidance stating that during July 2026 it had observed malicious cyber activity targeting over 100 internet-exposed systems in the Water and Wastewater Systems (WWS) Sector, commonly via programmable logic controllers connected directly to a cellular modem [1] [6]. Until that publication, federal agencies had not publicly quantified the number of systems affected [3].

The figure moved by a factor of more than three, roughly four weeks after the activity began, and it moved on the strength of an agency observation rather than a sector disclosure.

Reporting has linked the campaign to Iranian threat actors, and federal law enforcement indicated at the time that the activity was consistent with previous Iranian state-sponsored operations [2] [3]. CISA’s exposure reduction guidance describes the activity without naming an actor [1]. Attribution in this case remains contested rather than settled, and the analysis that follows does not depend on it.

The geographic picture is similarly incomplete. The US government has not stated how many states were affected, although at least 12 appears to be the working figure, with Minnesota, Michigan, South Dakota, Georgia, New Jersey and Alabama confirmed publicly [3]. Illinois does not appear on the list, but Illinois also has no regulation requiring water systems to notify law enforcement or the public of a computer intrusion [2]. Absence from a published list is not evidence of absence where no duty to report exists.

What Does the Revision Actually Show?

The number did not change because the campaign grew. It changed because the observer’s picture improved. Three features of the revision are worth separating.

The figure came from the observer, not the observed.

CISA stated that it observed the activity. That language points to agency telemetry, scanning and partner reporting rather than to aggregated victim notifications. A figure derived from what the observer could see is a measure of the observer’s reach, and it sets a floor rather than a ceiling.

The assets were not in the inventory.

In its 30 July 2026 alert, CISA advised that even water organisations with mature cyber security processes should validate their external connections, because the targeting included cellular modems installed by operators, vendors or system integrators that may not be documented or included in routine attack surface scans [4]. This is the mechanism behind the revision. A controller connected directly to a cellular modem has no route through the corporate network. It is internet-facing without being enterprise-facing, so an external attack surface management tool working from the organisation’s registered domains and IP ranges will not enumerate it.

Detection depended on process behaviour rather than security monitoring.

In the Minnesota incidents, utilities appear to have avoided serious consequences largely because staff noticed abnormal control behaviour and reverted to manual operation [7]. That is a real outcome and it reflects operational competence, but it is a thin margin, and it is not a security control in any repeatable sense. It also flatters the failure mode. Abnormal automation is an availability signal, and availability signals announce themselves. As we argued in Rethinking the CIA Triad in Operational Technology Environments, integrity failures behave differently, persisting undetected precisely because nothing stops working. An actor who had altered controller logic without disturbing the process would not have been found by the mechanism that found this one.

The structural explanation sits in the shape of the sector. Nearly 49,500 US community water systems fall under the Safe Drinking Water Act, and the EPA classifies around 81 per cent of them as small, meaning they serve 3,300 people or fewer [14]. The statutory duty to conduct a risk and resilience assessment under Section 1433 applies only to systems serving more than 3,300 people, which leaves roughly four in five community water systems outside the requirement altogether [14]. Reporting on the campaign indicates it fell mainly on small and rural utilities [6]. A sector composed predominantly of organisations with no assessment duty and no security function is a sector that will be counted by somebody else.

Who is Affected by the OT Detection Gap?

Water and wastewater operators.

Small and rural US utilities are the most acutely exposed, but the underlying condition is not specific to the United States. UK and EU water companies operate large estates of remote, unstaffed assets including pumping stations, reservoirs and treatment works, many of which report telemetry over cellular links precisely because a fixed connection is impractical. The asset class that CISA describes is the same asset class deployed across British and European water networks.

CNI operators outside the water sector.

Energy, transport and other operators of essential services run comparable distributed estates on comparable connectivity. Joint advisory AA26-097A named Government Services, Water and Wastewater Systems and Energy as directly affected sectors, and expanded the vendor scope from Rockwell Automation to Schneider Electric and Siemens [8]. The inventory blind spot travels with the architecture, not with the sector. Our analysis of the Polish energy sector incident documented the same dynamic through a different exposure route, where a single repeated configuration weakness across more than 30 facilities turned a site-level problem into a fleet-level one, and the full extent only became clear after the fact.

Boards and risk functions.

A sector risk figure that changes by a factor of three within four weeks is not a stable basis for board reporting, insurance placement or investment prioritisation. Anyone who briefed a board in early August on the basis of the initial figure understated the scale of the campaign by more than 70 systems, through no fault of their own. The relevant board question is not what the number is, but how much confidence attaches to it and what would have to be true for it to move again.

Suppliers, system integrators and equipment manufacturers.

CISA specifically identified connectivity installed by vendors and integrators as a category that may not be documented [4]. Remote access introduced during commissioning, or added to support a maintenance contract, can persist long past project handover without appearing in any register the asset owner maintains.

What Challenges Does This Create for Operators and Regulators?

Asset inventories do not contain the assets.

Cellular-connected controllers are frequently procured operationally, by engineering or maintenance functions and against an operational budget, rather than through an IT asset management process. They may never reach a configuration management database. In some estates they exist only in a project file or in an integrator’s records.

External attack surface management does not reach them.

Commercial attack surface tooling starts from an organisation’s known domains and address ranges. A controller sitting behind a mobile network operator’s address space is not in any of them, which means an operator can hold a clean external exposure report and still be internet-reachable. The NCSC made the same point in its alert of 27 August 2026, advising that organisations should not assume their OT is inaccessible from the internet without verifying it, because unintended exposure can arise through misconfigurations, legacy connections or unmanaged assets [13].

Reporting thresholds exclude the activity.

The UK NIS Regulations 2018 limit formally reportable cyber incidents to those that actually result in disruption to an essential service [5]. The July 2026 US campaign did not cause significant service disruption [3]. An equivalent UK campaign would, in many cases, generate no mandatory report at all. The Drinking Water Inspectorate’s experience illustrates this directly. Of 15 reports received from suppliers between January 2024 and October 2025, five concerned cyber security incidents affecting what the Inspectorate described as out-of-NIS-scope systems, and were shared for information because they were considered related to water supply resilience risks rather than because a duty required it [5].

Reform addresses the threshold but not the trigger.

The Cyber Security and Resilience Bill widens the definition of a reportable incident beyond significant disruption to capture incidents capable of significant impact, including pre-positioning, and introduces a two-stage process of initial notification within 24 hours and a full report within 72 hours to the competent authority and the NCSC [9] [10]. EU NIS2 already imposes a 24-hour early warning, a 72-hour notification and a final report within one month on essential entities, a category that includes drinking water and wastewater [11]. Both regimes start the clock when the entity becomes aware of the incident. Where the affected asset is undocumented and unmonitored, awareness may never arrive, and a widened threshold produces no report.

How IOActive Can Help

The revision from roughly 30 systems to more than 100 describes a measurement failure rather than a control failure. Nobody in the sector could state the scale of the campaign while it was running, and the figure that eventually emerged came from an agency looking in rather than from operators looking at themselves. Closing that gap means answering two questions with evidence rather than with documentation. What is actually connected, and would anyone notice if it were used.

IOActive has worked in industrial control environments since publishing the first proof-of-concept worm against the smart grid in 2009. The services below map onto the two questions this campaign leaves open.

Full Stack Security Assessments

The assets at the centre of this campaign were not hidden. They were undocumented, which is a different problem and a harder one, because no amount of scanning an organisation’s own address ranges will surface a controller that reaches the internet through a mobile network. Our Full Stack assessments examine an environment across its layers rather than at a single tier, covering internet-facing controllers and HMIs, the OT and IT boundary, the cellular modem paths that often give a field site its only route out, and the firmware and silicon of the devices themselves. The output is an inventory that has been verified rather than asserted, which is the precondition for every other step recommended below.

Red Team and Purple Team Services

The more uncomfortable question this campaign raises is not whether operators were exposed but whether they would have known. In Minnesota, detection came from control room staff noticing that automation was behaving abnormally [7]. That is a credit to the operators involved and it is not a control any organisation should expect to rely on twice. Adversarial testing answers the question directly, by establishing whether an intrusion at an unstaffed remote site produces a signal that anyone acts on. It is particularly suited to integrity attacks such as altered controller logic, which availability-focused monitoring is not built to catch. Purple team work then converts those findings into detection that the operator’s own staff can maintain, which matters more in operational environments than in enterprise ones because the meaningful signal is frequently a process anomaly rather than a network event. We set out the distinction between the two approaches in Red vs Purple Team, what’s the difference?.

Supply Chain Integrity

CISA was explicit that the cellular modems involved may have been installed by operators, vendors or system integrators, and may never have been documented [4]. That places part of the inventory problem outside the operator’s own records entirely. Our Supply Chain Integrity work assesses the security posture of technology providers and critical third parties, covering firmware, embedded systems, remote access arrangements and procurement processes, so that connectivity introduced during commissioning or under a maintenance contract is identified before it becomes someone else’s route in. For UK operators this maps onto the designated critical supplier powers in the Cyber Security and Resilience Bill [9].

If you would like to discuss how your organisation’s remote OT connectivity and detection coverage measure up against the activity described here, we welcome the conversation.

  1. Enumerate cellular and out-of-band connectivity as a separate exercise from the IT asset inventory. Network discovery will not find these assets, so the exercise has to be conducted through engineering teams, maintenance schedules and site records.
  2. Interrogate procurement and project documentation for purchases of modems, industrial routers and remote telemetry units, including those made under capital projects and maintenance contracts rather than IT budgets.
  3. Ask every OEM, system integrator and maintenance supplier directly whether connectivity was installed to support their own access, and whether that connectivity remains active.
  4. Apply CISA’s exposure reduction measures to whatever the exercise finds. Disconnect controllers from direct internet exposure, route remote access through a VPN or gateway rather than to the controller itself, enable and change default passwords, allowlist permitted source addresses, and hold a known clean controller image in case an actor changes the device password [1] [4].
  5. Treat process anomalies as a security signal. Define in advance which operational deviations trigger a security escalation rather than only an engineering response, and make sure control room staff know that route exists.
  6. Rehearse the 24-hour notification decision against a scenario involving unauthorised access with no service disruption. Establish who holds the decision that such an event is reportable, and how quickly that decision can be reached out of hours.
  7. Re-baseline the board risk picture once the inventory work is complete, and state explicitly what confidence attaches to the new figure and what would cause it to change.

Conclusion

The revision from roughly 30 systems to more than 100 is the most useful finding to come out of the July 2026 campaign, and it has little to do with the actors involved. It demonstrates that a sector could be targeted at scale, across at least a dozen jurisdictions, without the targeted organisations being the ones to establish how widely it had happened.

Regulatory reform on both sides of the Atlantic is moving in the right direction, widening what must be reported and shortening the time in which it must be reported. None of it changes the fact that a reporting obligation begins with an operator knowing something has occurred. For operators running remote assets on connectivity that nobody has catalogued, the work that closes the gap is inventory work, and it is available to be started now. As we set out in Cyber Attack Trends 2026, the environments an organisation depends on most are routinely the ones it monitors least, and that ordering is a choice rather than a constraint.

References

[1] CISA. Internet Exposure Reduction Guidance. https://www.cisa.gov/resources-tools/resources/exposure-reduction

[2] Goudie, C., Capitanini, L. and Halder, N. Government admits water system cyberattacks were worse than first reported. NBC Chicago, 26 August 2026. https://www.nbcchicago.com/investigations/government-admits-water-system-cyberattacks-were-worse-than-first-reported/3980961/

[3] Kovacs, E. CISA: Over 100 Internet-Exposed Water Systems Targeted in July Cyberattacks. SecurityWeek, 26 August 2026. https://www.securityweek.com/cisa-over-100-internet-exposed-water-systems-targeted-in-july-cyberattacks/

[4] CISA. CISA Urges Water and Wastewater Systems Sector to Protect OT Against Activity Targeting PLCs, 30 July 2026. https://www.cisa.gov/news-events/alerts/2026/07/30/cisa-urges-water-and-wastewater-systems-sector-protect-ot-against-activity-targeting-plcs

[5] Martin, A. Hackers are attacking Britain’s drinking water suppliers. The Record, 3 November 2025. https://therecord.media/britain-water-supply-cybersecurity-incident-reports-dwi-nis

[6] More than 100 water systems were hit in July cyberattacks. The Register, 26 August 2026. https://www.theregister.com/cyber-crime/2026/08/26/more-than-100-water-systems-were-hit-in-july-cyberattacks/

[7] IOActive. When the Advisory Arrives First: Minnesota’s Water Utilities and the Limits of Warning. https://www.ioactive.com/when-the-advisory-arrives-first-minnesotas-water-utilities-and-the-limits-of-warning/

[8] CISA, FBI, NSA and partner agencies. Iranian-Affiliated Cyber Actors Exploit Programmable Logic Controllers Across US Critical Infrastructure (AA26-097A), originally published 7 April 2026, updated 22 July 2026. https://www.cisa.gov/news-events/cybersecurity-advisories/aa26-097a

[9] House of Commons Library. Cyber Security and Resilience (Network and Information Systems) Bill 2024-26, 2026-27, research briefing CBP-10442. https://commonslibrary.parliament.uk/research-briefings/cbp-10442/

[10] Department for Science, Innovation and Technology. Cyber Security and Resilience (Network and Information Systems) Bill factsheets: Summary of the Bill. https://www.gov.uk/government/publications/cyber-security-and-resilience-network-and-information-systems-bill-factsheets/summary-of-the-bill

[11] Directive (EU) 2022/2555 (NIS2), Article 23. Incident reporting obligations for essential and important entities.

[12] Federal News Network. CIRCIA, other big cyber rules expected to get finalized this fall, 10 July 2026. https://federalnewsnetwork.com/cybersecurity/2026/07/circia-other-big-cyber-rules-expected-to-get-finalized-this-fall/

[13] NCSC. Disruptive cyber activity highlights risk from internet-exposed systems and edge devices, 27 August 2026. https://www.ncsc.gov.uk/news/disruptive-cyber-activity-highlights-risk-from-internet-exposed-systems-and-edge-devices

[14] Congressional Research Service. Cybersecurity of the Municipal Water Sector: Background and Issues for Congress, report R48556. https://www.congress.gov/crs-product/R48556

INSIGHTS | October 9, 2026

Secure Product Development Lifecycle Requirements

A final penetration test can miss a design choice that gives attackers an easy path later. An open debug port, a weak update process, or an unknown dependency can affect the whole product. For CISOs, CTOs, and product security leaders, secure product development lifecycle requirements define what to protect, which controls to build, how to test for vulnerabilities, and who owns each security decision.

In practice, these requirements span six connected areas: security goals, threat modeling, hardware and firmware controls, component records, release checks, and postmarket response. Together, they answer two practical questions: what must the team do, and what evidence shows that the work is complete?

  • Identify assets, trust boundaries, and security goals.
  • Set controls for hardware, firmware, software, suppliers, and updates.
  • Test each control and record the result before release.
  • Prepare for reports, fixes, customer notices, and end of support.

Secure Product Development Lifecycle Requirements at a Glance

The table below puts the requirements first, then shows what each one tests, what the team should do next, and what evidence can support a release decision.

Secure Product Development Lifecycle Requirements and Evidence

RequirementWhat it meansWhat it tests or controlsWhat to do nowEvidence and service fit
Security goals and asset inventoryName key assets, users, data, interfaces, and trust boundaries.Tests whether the design protects the right things.Approve an asset and data-flow map.Risk record and architecture review.
Threat modelRecord attack paths, impact, controls, and owners.Tests whether key abuse cases have a planned response.Review threats after major design changes.Threat model and assessment plan.
Hardware and firmware securityProtect debug ports, keys, boot paths, recovery, and updates.Tests whether an attacker can bypass trust or persist.Define secure boot, signing, key use, rollback, and factory controls.Hardware, firmware, and reverse-engineering assessment.
Component and SBOM managementTrack components, origin, version, and support status.Tests whether the team can find exposure after a change.Keep the SBOM current and define triage steps.Component review and supply chain assessment.
Secure implementationBuild security into code, settings, interfaces, and build systems.Tests for coding flaws, weak boundaries, and unsafe defaults.Use peer review, analysis, fuzzing, and build controls.Review findings and signed artifact records.
Security validationCombine design, code, hardware, abuse-case, and penetration testing.Tests whether controls work under attack.Link each key requirement to a test, result, fix, and owner.Release security record and risk decision.
Release and deployment integrityProtect images, secrets, update channels, and recovery.Tests whether tested files match shipped files.Sign releases, protect secrets, and test offline recovery.Hashes, signing logs, and release runbook.
Vulnerability response and supportDefine intake, severity, fixes, notices, and end-of-support ownership.Tests whether field risk can be handled after launch.Assign owners and exercise the response path.Response plan and postmarket records.

The matrix starts with the requirements because leaders need to see the control set before reviewing the process behind it. Its final column also points to the evidence and assessment work that makes those controls credible. The next step is to establish the assets, boundaries, and threats that determine which requirements matter most.

The table turns broad security goals into clear outcomes. Each outcome needs an owner, a test, and supporting evidence. NIST’s Secure Software Development Framework groups related work into four areas: prepare the organization, protect software, produce well-secured software, and respond to vulnerabilities. Teams can apply that model across hardware, firmware, cloud services, factories, and field support.

Start With Architecture and Threat Modeling

Security planning should begin before development with a map of key assets, trust boundaries, user roles, data flows, safety impacts, and external interfaces. Include both the product and the systems that support it.

For each major attack path, record the asset at risk, likely access, possible harm, required control, test method, and owner. This record turns a broad goal into a design task that teams can review and track.

A useful requirement is testable: “The boot chain checks approved firmware before it runs.” Add related rules for key approval, recovery, and verification failure so engineers and assessors can review the same target.

Threat modeling should also trigger a review when the product changes. A new radio, cloud endpoint, supplier, privilege, or update path can alter the attack surface, so do not wait for the next scheduled test. NIST describes SSDF as a basis for planning and ongoing improvement, not as a fixed checklist.

Architecture and Threat-Model Readiness

Architecture questionReady signalIf the answer is “no”
What are the high-value assets?Owners and impact are recorded.The scope may miss a key asset.
Where are the trust boundaries?Interfaces and data flows are mapped.Attack paths may remain untested.
Which controls reduce each risk?Each risk has a control and owner.Work may start without a clear target.
How will each control be tested?The test and pass result are defined.Release evidence will be weak.Architecture question
Ready signal
If the answer is “no”
What are the high-value assets?
Owners and impact are recorded.
The scope may miss a key asset.
Where are the trust boundaries?
Interfaces and data flows are mapped.
Attack paths may remain untested.
Which controls reduce each risk?
Each risk has a control and owner.
Work may start without a clear target.
How will each control be tested?
The test and pass result are defined.
Release evidence will be weak.

The readiness check shows whether the security plan is specific enough to guide design work. Once assets, boundaries, and tests are named, the team can apply those requirements to the physical device, firmware, software, and supply chain.

Cover Hardware, Firmware, and Dependencies

Connected products cross physical, embedded, software, and operational layers. A weak bootloader can expose a product, but so can an exposed board port, device key, update server, or open-source package.

The requirement is not simply to “secure the device.” Define the control at each layer, then show how those layers work together.

Hardware requirements should cover trusted parts, debug access, key storage, physical access, fault handling, interfaces, and factory controls. Firmware requirements should address signed updates, key rotation, privilege limits, logs, recovery, and rollback. Software requirements should cover authentication, access rights, input handling, secrets, interfaces, and safe settings.

Dependency records need the same level of care. Track component origin, version, license, maintainer, support status, build system, and signing system. Define how the team will assess a new flaw, then set criteria for when to patch, mitigate, or retire a component.

IOActive treats component reviews as part of secure product development, with work that spans architecture and configuration review, static analysis, and dynamic analysis. Its full-stack assessment model extends from physical and semiconductor layers through software, process, governance, and supply chain security. That breadth helps when a risk crosses team or supplier lines.

Security Requirements by Product Layer

LayerRequirement examplesEvidence to retain
HardwareRestrict debug access, protect secrets, and define fault response.Schematics, settings, lab findings, and fix status.
FirmwareVerify signed images, limit rights, and test recovery.Boot logs, key design, update tests, and failure cases.
SoftwareReview entry points, dependencies, interfaces, and defaults.Code review, analysis results, SBOM, and issue records.
Factory and supply chainControl provisioning, build inputs, and signing access.Supplier records, build records, access logs, and approvals.

The layer view makes ownership clearer. It also shows why a single application test cannot cover every product risk. With the control boundaries defined, the next section focuses on the evidence and assessment methods needed before release.

Validate Before Release

Use more than one assessment method because each one examines a different risk. Design review checks the security model, while code review and analysis examine the implementation. Fuzzing and abuse-case testing exercise unusual inputs and workflows, and penetration testing shows whether an attacker can combine flaws into a practical path. Start early so the team has time to fix what it finds.

IOActive recommends starting security testing during code development because early findings leave time to change an interface, replace a component, or revise a protocol. The same principle matters for hardware and firmware, where late changes can affect suppliers, tools, certification, and field updates.

Create a release security record that links each key requirement to its design, test result, known limit, fix status, and owner. Include the update system, factory process, physical attack surface, and residual-risk decision.

A release is not ready simply because a test took place. It is ready when the evidence shows that required controls work, every finding has an owner, and an accountable approver has accepted any remaining risk.

Deployment needs validation as well. Confirm that production images match tested images, sign release files, protect provisioning secrets, and set safe defaults. Test recovery for devices that are offline or hard to reach, and record who can approve an emergency release and how customers will receive it.

Pre-Release Validation Gates

Validation gateReady whenNot ready when
Design and threat modelMajor risks have controls, owners, and tests.High-impact risks remain assumptions.
Code and component reviewFindings are fixed, accepted, or tracked.Critical findings lack a decision or owner.
Hardware and firmware testingBoot, update, recovery, and physical access are assessed.Testing covers only the network or app layer.
Release integrityThe shipped file matches the approved, signed file.Production steps cannot be checked.
Residual riskA named approver accepts documented limits.The team relies on a verbal decision.

These gates define readiness in operational terms. They connect technical findings to release ownership and make it harder for unresolved risk to disappear between testing and launch. The next requirement is a plan for issues that surface after the product reaches customers.

Plan for Vulnerabilities and Regulatory Duties

Before release, define a disclosure channel, intake process, severity model, patch flow, customer notice plan, and end-of-support policy. Assign owners across security, engineering, compliance, product, and operations so the response path is clear.

Exercise that path with failure cases, including devices that are offline, low on storage, or unable to reach the service.

The European Union Cyber Resilience Act places duties across the planning, design, development, and maintenance of covered products with digital elements. It also requires manufacturers to handle vulnerabilities throughout the product lifecycle. The European Commission’s manufacturer guidance highlights risk assessment, secure defaults, access control, cryptography, updates, technical records, support periods, and vulnerability handling.

The Act entered into force on December 10, 2024. Its reporting duties apply from September 11, 2026, while its main duties apply from December 11, 2027.

For medical-device makers, FDA cybersecurity guidance issued on February 3, 2026 addresses device design, labeling, and premarket records. It also covers Section 524B, including plans and procedures, processes for reasonable cybersecurity assurance, and software bills of materials for qualifying cyber devices. Because applicability depends on the product and market, compliance teams should map the rules to the device and submission path.

Postmarket Vulnerability and Support Readiness

Postmarket controlReadiness questionEvidence of readinessIf not ready
Vulnerability intakeCan researchers report issues and get an acknowledgement?Public channel, triage owner, and intake record.Reports may be lost or delayed.
Severity and remediationCan the team rank issues and set response targets?Severity model, decision log, and owners.High-risk issues may wait too long.
Update deliveryCan the team build, test, sign, and ship a fix?Exercised update path and release runbook.A field flaw may stay open.
Customer communicationCan affected customers learn what to do?Notice template and support workflow.Customers may keep an unsafe setting.
Support periodWho owns security work through the end of support?Named owner, dates, budget, and retirement plan.Field risk may outlast the team.

The postmarket table turns support from a broad promise into a set of testable responsibilities. It also exposes gaps that can leave customers without a clear reporting, patch, or retirement path. Those responsibilities must then be assigned to owners and tied to review gates.

IOActive’s supply chain work treats resilience as both a technology and an operations issue. Its research record includes hardware, firmware, embedded, wireless, and software investigations. That range reinforces why product security evidence should follow the product across layers.

Turn Requirements Into Owned Release Gates

A secure product lifecycle becomes practical when each requirement is specific, owned, testable, and tied to a decision. Start with the main table, then convert each row into a requirement statement with an owner, acceptance test, evidence location, and review trigger.

“Protect firmware updates” is too broad to approve. A stronger set of rules names image signing, key custody, failed verification, rollback, recovery access, and the test for each control. The same pattern works for threat models, SBOMs, factory provisioning, response, and support.

Use a simple review cycle that revisits the requirements at architecture review, major design change, code-complete review, release review, and postmarket incident review. This keeps decisions visible as the product, supplier, or threat changes.

Ownership and Review Gates

Requirement recordOwnerAcceptance evidenceReview trigger
Security goalProduct security leadApproved risk and asset scopeNew product or major use change
Technical controlEngineering ownerDesign record and test resultArchitecture or code change
Component recordSoftware or supply chain ownerCurrent SBOM and triage decisionNew dependency or supplier change
Release gateRelease ownerSigned artifact and risk approvalRelease candidate or emergency fix
Support commitmentProduct and operations ownersUpdate, disclosure, and end-of-support planLaunch, incident, or support change

This ownership model closes the loop between a written requirement and the decision to ship or continue support. It gives product, engineering, security, and operations a shared review structure, which sets up the final release check below.

IOActive combines research with hands-on expertise across hardware, embedded systems, software, and full-stack assessments. That combination can help teams assess gaps, test controls, and build evidence that supports product, risk, and compliance decisions.

Make Security a Product Requirement

Use the final check below to confirm that the release decision has a clear basis.

Final Secure Release Check

Final checkReadiness signal
Every requirement has an owner.Accountability is clear.
Every key control has a test and evidence record.The release decision is supportable.
Postmarket owners and dates are set.Field risk has a clear path.

The final check confirms that the process is ready beyond the technical test itself. If any answer is no, the release decision needs a named owner, a documented action, or an explicit risk acceptance before launch.

Secure product development lifecycle requirements are more than a final testing checklist. They define the controls for design, build, validation, deployment, and support.

When every requirement has an owner, test, evidence record, and review trigger, security becomes part of how the product is built and maintained. That structure gives teams a clear basis for release and support decisions.

Sources

  1. National Institute of Standards and Technology, “Secure Software Development Framework (SSDF).”
  2. IOActive, “Component Reviews.”
  3. European Commission, “Cyber Resilience Act.”
  4. European Commission, “Cyber Resilience Act: Manufacturers.”
  5. U.S. Food and Drug Administration, “Cybersecurity in Medical Devices: Quality Management System Considerations and Content of Premarket Submissions.”
  6. U.S. Food and Drug Administration, “Cybersecurity in Medical Devices: Quality Management System Considerations and Content of Premarket Submissions, document issued February 3, 2026.”
  7. IOActive, “Supply Chain Integrity.”
  8. IOActive, “IOActive Research Timeline.”
INSIGHTS | October 6, 2026

Cyber Risk Management Strategies: Six Ways to Align Security With Business Priorities

Cybersecurity analyst reviewing business systems as part of a cyber risk management strategies.

Recent IOActive research on 2026 attack trends points to a recurring problem: attackers target systems that companies rely on the most, but watch the least, including operational technology (OT), firmware supply chains, and AI-enabled development. That raises a difficult question for security leaders: Which risks deserve investment first?

The answer is not always the vulnerability with the highest technical severity. A useful cyber risk management strategy links technical risk to business impact, tests whether attack paths are realistic, and directs funding toward the risks most likely to disrupt the business.

“The most effective cyber risk management strategies prioritize business impact alongside technical risk.” – IOActive Security Team

Six Pillars of Business-Aligned Cyber Risk Management Strategies

PillarsWhere to StartKey Areas CoveredQuestion to Consider
Link risk to business impactFocus on risks that could disrupt critical operationsCritical services, dependencies, recoveryWhich services and dependencies need protection first?
Test priorities through offensive securityTest whether realistic attack paths can achieve business objectivesPenetration testing, Red Team, threat researchHow well do controls detect and respond to realistic attacks?
Manage connected exposureEvaluate risks beyond the organization’s direct controlThird parties, supply chains, OTWhich dependencies could affect resilience?
Govern AI by impactMatch oversight to the impact of failure or misuseAI-generated code, automation, dataWhere are more controls required?
Turn findings into decisionsEstablish ownership, thresholds, and funding prioritiesGovernance, risk appetite, reportingWhat should be fixed, accepted, or escalated?
Keep testing securityConfirm that controls remain effective as conditions changeRetesting, Purple Team, detection, recoveryHow does the organization know risk is improving?

These six pillars move from prioritization to validation, giving leaders a repeatable way to decide what to test, fund, and revisit.

A cyber risk management strategy should begin with the business services that cannot tolerate long outages, like production, payments, clinical operations, customer access, or safety processes.

Why it is essential

A vulnerability’s priority depends on what it could affect. Business impact may include lost revenue, downtime, safety consequences, regulatory exposure, reputational harm, data-integrity problems, or recovery difficulty. A moderate weakness may deserve urgent attention if it sits between an attacker and a critical process.

The key question is not simply, “How severe is this vulnerability?” It is, “Could this weakness create a credible path to business failure?”

What to do next

For each critical service, identify the dependencies that would have to fail for the service to stop or operate unsafely. Then rank those dependencies according to access, consequence, recoverability, and the likelihood that an attacker could reach them.

One useful way to structure this conversation is the NIST Cybersecurity Framework 2.0. The framework gives security, technology, risk, and business leaders a shared language for identifying, governing, protecting, detecting, responding to, and recovering from cybersecurity risk.

Used this way, the framework helps turn isolated findings into priorities the business can understand and fund.

Test Priorities Through Offensive Security

Offensive security tests whether realistic attack paths could reach a defined business objective. It provides evidence that a risk register or compliance assessment cannot provide on its own.

Why it is essential

An attacker may need to combine several moderate weaknesses to reach a sensitive system. A penetration test can validate a defined application, network, or product. A Red Team exercise can test whether an attacker can reach a business goal across technical, physical, and human layers. A Purple Team exercise can then bring offensive and defensive teams together to evaluate detection, response, and control effectiveness.

What to do next

Start with the decision the assessment needs to support. Leaders may need to know whether a compromised vendor account could reach production, whether a stolen credential could access a critical application, or whether security operations would detect a multi-step attack.

Choose the assessment based on that question rather than a generic checklist. The result should show which weaknesses could be combined, which controls would interrupt the attack, and where further investment would reduce uncertainty or exposure.

Manage Connected Exposure Across Third Parties and OT

A business-aligned strategy must include systems and organizations outside the traditional security boundary. Vendors, cloud providers, software suppliers, remote-access channels, and operational technology may all support critical business services.

Why it is essential

A supplier compromise could interrupt operations, expose sensitive data, alter production, or delay recovery. Third-party risk should therefore reflect more than a vendor’s questionnaire score. It should account for access, dependency, concentration, recoverability, and business consequence.

OT creates an additional concern because a security incident may affect physical processes. In some environments, an integrity failure may be more serious than an outage if an attacker can manipulate commands, sensor data, or operating conditions.

What to do next

Map the suppliers and external connections that support each critical service. Identify which accounts, interfaces, software components, and remote-access paths could provide entry into the environment.

For OT, evaluate security decisions alongside safety, continuity, recovery, and the limits of specialized systems. The goal is to understand which dependencies could create a credible path from an external compromise to operational disruption.

Govern AI Adoption According to Business Impact

AI should not be governed as a single risk category. The right controls depend on what the system can access, influence, or automate.

An internal productivity assistant presents a different risk from an AI tool that generates live code, handles customer data, approves transactions, or influences operational decisions.

Why it is essential

The consequences of an AI failure depend on where the system sits in the business. An incorrect answer may be inconvenient in one workflow but costly, unsafe, or difficult to reverse in another.

If an incorrect or manipulated result could cause material harm, keep a person involved in approval and define when the system must stop. If the system can reach sensitive data, production systems, or consequential decisions, limit access, log use, and monitor the system. If its output can affect a release, customer, or operational process, test it before deployment and continue checking it in production.

What to do next

A practical AI risk review should ask:

  • What happens if the system produces an incorrect or manipulated result?
  • What data, systems, or decisions can the system influence?
  • What validation occurs before the output reaches production or a customer?

Use the answers to set the controls. Keep a person involved when an output could cause material harm, restrict and monitor access to sensitive data or production systems, and require testing before release and during use. Review the code, data, integrations, access paths, and workflows around the system, then retest them as the system changes.

Turn Risk Findings Into Investment Choices

A technical finding has limited value until someone decides what to do about it. Governance should give security and business leaders a consistent way to determine whether a risk requires remediation, mitigation, formal acceptance, or escalation.

Why it is essential

Without clear ownership and decision thresholds, unresolved exposure can remain in a risk register without receiving meaningful attention. Explicit decisions also help executives compare security investments with other business priorities.

The most useful recommendation explains what an investment changes. A Red Team exercise may reduce uncertainty about attack paths, while improved monitoring may shorten detection and containment. Those are different outcomes and should be evaluated accordingly.

What to do next

Assign each high-impact risk an owner, a defined consequence, a decision deadline, and a treatment plan. Document whether the organization will fix the weakness, reduce its likelihood, limit its impact, monitor it, accept it, or escalate it.

Give every accepted or mitigated risk a review date so the decision remains visible and accountable.

Keep Testing and Adjusting Cyber Risk Management Strategies

Cyber risk management strategies need regular review as the business, suppliers, technology, and threat landscape change. Organizations need evidence that remediation, detection, response, and recovery still work.

Why it is essential

A control that worked six months ago may no longer protect the same system, service, or attack path. Organizations need evidence that remediation worked and that detection, response, and recovery capabilities remain effective.

What to do next

Retest important attack paths after remediation. Review dependencies after major changes. Use Purple Team exercises to validate detection and response, and measure time to detect, contain, recover, and restore key services.

Threat research should also update the assumptions behind security decisions. The goal is not more testing for its own sake. It is a feedback loop:

Identify → Prioritize → Test → Improve → Validate → Reprioritize

This sequence helps organizations determine whether security investment is reducing business risk or simply generating more technical findings.

Invest in the Risks Most Likely to Disrupt the Business

Effective cyber risk management strategies help leaders identify the attack scenarios most likely to disrupt operations, assess whether current defenses would withstand them, and direct investment where it will reduce risk.

That requires more than vulnerability discovery. It requires business context, adversarial testing, governance, and continuous validation.

IOActive combines research, offensive testing, and advisory services to help organizations examine those questions across AI/ML, supply chains, OT/ICS, hardware, firmware, and enterprise environments. The result is a clearer basis for deciding what to fix now, what to monitor, and what risk the business can accept.

GLOBAL THREAT GROUP, INSIGHTS, RESEARCH | October 1, 2026

LLM-Assisted Vulnerability Research: Finding Real Bugs with Code-Reasoning Models

Introduction

Point a code-reasoning model at a codebase and it reads through it far faster than I can, then hands back a long list of things that look like bugs. Generating that list is the easy part now, but most of it is noise. Almost every candidate falls apart the first time I try to trigger it against a real build, and the handful that survive still have to be proven before they count as findings. Getting from that list to a proven bug is the slow, deliberate part of the job.

In this post I walk through the workflow that I use to close that gap, and two real bugs it has produced. Both are now fixed in Angular and rated HIGH severity:

  • CVE-2026-68945: a server-side render cache that could hand one visitor’s response to the next visitor, skipping the backend’s authorization check entirely.
  • CVE-2026-69151: a translation-file path that let lower-trust text compile into a live JavaScript event handler, turning a localization bundle into a script-injection vector.

These two are the CVEs I can name today; more from the same process are still working through coordinated disclosure.

Neither came from asking a model to “find bugs.” Both came from a disciplined loop: work out the rules a project’s code must never break, from its patch history and its own design, then keep the model’s attention on one small piece of code at a time, drive it through four focused audit passes, and believe nothing until I have proven it myself in a real runtime. The model does the reading and the guessing. I own the threat model, the runtime, and the final call.

That division of labor, not the automation, is what holds the whole thing together. The rest of this post builds it up, starting with why the obvious shortcut (just asking a model to find bugs) doesn’t work.

Why “Find All the Vulnerabilities” Fails

Ask a large language model (LLM) to “find security bugs in this repository” and it will answer at length, confidently – and almost none of it will be worth acting on.

What comes back is a list of plausible-looking weak points with no sense of which ones an attacker can reach, textbook bug patterns matched onto code that never runs, and not one claim that the model has tried to disprove. Separating the real from the decorative lands right back on you, now scaled up to the length of the model’s output.

A bare request gives the model no notion of reachability, no trust boundary, and no idea which bug classes a maintainer would actually accept. That means it falls back on the only thing it can do: it matches shapes that look like vulnerabilities and reports them with even confidence, whether they sit on a hot path or in dead code. The model writes clean, persuasive analysis, but nothing in the request forces it to be true.

Constrain the request to a single testable claim, anchored in the target’s own history, and the same model behaves differently:

Recent accepted vulnerabilities in this component involved validation/use mismatches. A patch introduced cumulative length validation in one path. Identify sibling paths that still validate entries independently while dispatching batches to a backend that consumes cumulative state. Demonstrate or refute this in the product runtime, with a negative control and a fixed-version comparison.

Now the model has a reachability target, a boundary that defines impact, and a claim that can be caught when it’s wrong. This still generates candidates, but each one arrives with the terms of its own refutation attached.

The difference between the two prompts is not the model or its size, but the question. And a good question starts from a threat model.

Threat Modeling: Rules the Code Must Never Break

Before I send any code to a model, I build a compact threat model from the project’s own security history: its advisories, its commits, its patch diffs. The point isn’t only to re-hunt old bugs. It’s to learn how the software expects its data to behave, so I can then look for places where that assumption quietly fails.

The output of that work is a short list of invariants. An invariant is a one-sentence rule the code assumes is always true and that a bug would break, for example, “the byte count validated at the perimeter must equal the amount the backend actually consumes.” That is the whole idea. An old validation-patch advisory becomes exactly that kind of rule. An advisory about a use-after-free (a bug where code keeps using an object after it’s been freed) becomes “no object may keep using itself after calling a callback that can destroy it.”

While an invariant is the rule the code must hold, once a bug shows that rule being broken, a variant is any other location where the same rule is broken in the same way.

Prior reported bugs make the hunt richer, because each one hands you an invariant the code already got wrong and a family of variants to chase, but they are not required. Where there are none, you derive the invariants from the code’s own contracts, a cache key that must stay unique or a trust boundary that must hold. This is where a model and an expert outrun what either does alone: the model maps the sinks and their connections across the whole surface far faster than a person could, while the researcher decides which invariants matter and where they break. The threat model is the method, and the pairing is what makes it powerful.

This is also why “find a use-after-free” is a useless prompt, while “determine whether this callback can free the parent object before the next line reads a member of it” is a good one. The first is a bug category, the second a specific claim a model and I can both test.

Nothing about this is specific to open-source. The method is the same whether the target is a public repository, a client’s proprietary codebase, or a closed black box, and what changes is only how much of the history is handed to you. Open-source projects give it away in public commits and advisories, which is why the examples in this post are open-source. On a closed target, you assemble the same ground truth yourself from decompiled interfaces, architecture documents, past vendor disclosures, and dynamic traces, and that is the slower, harder version of the identical work. A model can’t invent a threat model from nothing, and it works only from the evidence you give it.

Figure 1 – From a patch to its forgotten sibling.

Context Discipline: The Token Budget

Compressing history into an invariant is wasted effort if the model loses that invariant halfway through the job, which is exactly what happens when you ignore how its context works. A model doesn’t have your repository open the way an editor does. On every turn it sees one block of text – your prompt, the conversation so far, the code you pasted, the tool output that came back – and nothing else. That block is the context window, measured in tokens (roughly ¾ of a word each), and it is finite. Almost every failure I hit traces back to how that budget gets spent. The most relevant reasons for context failure are these three:

Lossy compaction. When a conversation nears the window limit, the tooling summarizes older turns to make room. Summaries keep the story (“found a validation gap”) and throw away the specifics upon which a finding depends: the exact line number, the build flag, the crash offset. After a couple of rounds of this, a session can sound completely confident while no longer holding a single piece of usable evidence. That’s the most dangerous failure mode, because nothing looks broken.

Degraded recall in the middle. A model recalls what sits at the start and end of a long context far better than what is buried in the middle. The effect has a name, “lost in the middle,” and it has outlasted several generations of far larger context windows. A 2025 context rot study found every one of eighteen frontier models still degrading as their input grew. That is the problem here, because the invariant, the one thing that has to hold from the first turn to the last, is exactly what sinks into that middle while the model keeps reasoning as if it still had it.

Cache invalidation. Reasoning over a large context is only affordable because the tooling caches the processed prefix. Churn the conversation and that cache goes cold, and every turn starts paying the full cost of reading everything again.

The fix is not a bigger window. That just moves the limit without solving the recall decay. The fix is to keep the working slice small enough that the invariant, the code under test, and the oracle (the check that separates a vulnerable build from a fixed one) all fit in the high-recall region at once. Everything else goes to disk.

Before I pause a session, I write a short HANDOFF.md at the repository root – the pinned commit, the current artifact, the live hypotheses, the dead ends already ruled out – so the next session resumes without re-deriving state. If that note runs longer than a page, the slice was too big and I split it.

Figure 2 – Keeping the slice in high-recall context.

The Four Audit Passes

With a threat model in hand and a list of candidate code paths to check, I run the model through four audit passes. Each one has its own input and its own output.

  1. Patch-diff variant farming. A patch shows the exact line the maintainers changed, and the code around it shows the neighborhood they left alone. I ask the model to find sibling paths that still contain the old, pre-patch logic. This is my highest-yield pass by a wide margin.
  2. Parser and serializer differentials. When a system implements the same concept more than once – two URL parsers, two header processors, two cache-key generators – those implementations can disagree, and the disagreement is a bug. I list the pairs and ask for inputs where they produce different results, aiming at request smuggling, server-side request forgery (SSRF), or cache confusion.
  3. Symmetry and dual checks. For every input-validation check, I look for its output twin: the cache layer, serializer, or redirect handler that’s supposed to enforce the same rule on the way out. A missing twin is a strong candidate.
  4. Cross-framework transfer. Once a bug pattern works in one target, I test sibling frameworks for the same underlying assumption. If it replicates, that’s a class-level design flaw, not one project’s slip.

Only the first pass looks backward at patches. The other three go looking for attack surface nobody has catalogued yet.

Those passes hand back a list of candidate bugs. I cut each surviving candidate down to a slice of under a hundred lines and send it through a dual-model gate, where one session is prompted to prove the bug exploitable and another, handed the same slice with no prior context, is asked to prove it safe. This is not a vote, because two runs of the same model share the same blind spots. I treat it as a disagreement detector instead.

When both sessions call the bug real, it still owes me a runtime proof; when both call it safe, I drop it; and a split, which flags the non-obvious edge cases, is the most useful of the three. The gate only filters, though, and whatever comes out of it I verify by hand, reading the code and reproducing the behavior myself, because two models agreeing is not proof.

Figure 3 – Four audit passes into a dual-model gate.

What a Verified Finding Looks Like

Before any of this touches a runtime, each candidate gets a spec card, four lines that fix exactly what is being claimed and what would prove it. Here’s one, from a sanitized browser-graphics example – a validation/use mismatch, where the check validates each draw command on its own but the backend runs the whole batch and walks the write cursor past the allowed buffer:

Invariant:  ValidateBatch must validate the cumulative byte count
            consumed by SubmitBatch, not the largest single entry.
Attacker:   A web page controls the draw list and the bound range.
Oracle:     The second draw must fail if draw1 + draw2 exceeds the
            bound range. A vulnerable build writes past the range;
            a fixed build returns an API error.
Stop:       Do not claim High unless the write crosses an allocation,
            ownership, process, origin, or authority boundary.

The oracle is the line that does the work, the exact condition that tells a vulnerable build from a fixed one. Here the oracle is checked across three runs, and the contrast between them is the proof:

separate_draw_control:    second_draw_error = INVALID_OPERATION
                          bytes_after_bound_changed = 0

batched_draw_vulnerable:  batch_error = NO_ERROR
                          bytes_after_bound_changed = 64

batched_draw_fixed:       batch_error = INVALID_OPERATION
                          bytes_after_bound_changed = 0

The first run is the negative control, where single checks reject the bad bounds. The second shows the bypass under batched execution, and the third confirms the fix. One log line would prove nothing, but the contrast across all three is what a triager can trust.

This example shows one more thing: because the writes stayed inside memory the calling page already owned, this was a constrained primitive (a real but limited capability), not full memory corruption. That distinction is the difference between a Medium and a High, and I’ll come back to it. The productive next question is never “can I make this proof-of-concept louder?” It’s “where else does this invariant fail?”

Figure 4 – A validation/use mismatch: control vs affected.

Two Real Findings in Angular

Here’s the method producing real, accepted bugs, both reported, confirmed, and patched upstream. One came from a forward-looking differential, the other from a patch variant.

CVE-2026-68945: two requests, one cache key

Advisory: GHSA-jhpw-976m-542j. Rated HIGH (CVSS v4.0) by the assigning authority.

The assumption, from history. Angular’s server-side rendering (SSR) builds the page on the server before sending it to the browser, and it caches the HTTP responses it fetches so the browser can reuse them during hydration instead of re-fetching. Any cache like that rests on one rule.

The invariant. Two HTTP requests that could receive security-distinct responses must never share a cache key.

The hypothesis (Pass 2, serializer differential). If the code builds cache keys by turning request parameters into a string, is there more than one way to write “the same” string? There was. The key generator joined repeated parameters with commas, so two genuinely different requests collapsed onto one key:

GET /api?role=user&role=admin   →  key "role=user,admin"
GET /api?role=user,admin        →  key "role=user,admin"

Figure 5 – Two requests, one cache key (CVE-2026-68945).

The proof. The oracle was a backend hit-counter, and two distinct requests produced exactly one backend call. The second visitor was served the first visitor’s cached response straight from the transfer cache, never reaching the backend’s authorization check. Angular fixed the key serialization in 20.3.27, 21.2.19, and 22.0.2 (PR #68571).

CVE-2026-69151: a translation file that could inject a script

Advisory: GHSA-jj27-h5hq-8×99. Rated HIGH (CVSS v4.0) by the assigning authority.

The assumption, from history. Angular’s template compiler treats internationalization (i18n) files as lower-trust: translators are supposed to supply text, not code. That’s a trust boundary, and trust boundaries are exactly what threat modeling tells you to test.

The invariant. Lower-trust translation content must never compile into an event handler.

The hypothesis. An earlier fix had already closed one hole where translated content bypassed the normal attribute checks. So, what other attributes still slip through the same translation path? Event handlers did. The compiler accepted i18n-onerror and other i18n-on* attributes, which meant a tampered translation file could drop live JavaScript into a static event handler.

The proof. The demonstration is a compile-time differential rather than a memory trace. Bind onerror on an element directly and the compiler rejects it. Mark the same attribute i18n-onerror and it passes the i18n collection path and compiles into the localized build intact. A translation file supplying that attribute’s value then controls a live handler, which is exactly what the advisory documents, a lower-trust translation file replacing a benign onerror=”void 0″ with arbitrary JavaScript that runs in the application’s origin. Angular fixed it in 20.3.27, 21.2.19, and 22.0.1 (PRs #68821 and #69306).

Figure 6 – i18n bypass: onerror vs i18n-onerror (CVE-2026-69151).

The bug wasn’t a sanitization slip but a broken contract between the compiler and untrusted input, and that input is realistic: localization bundles routinely come from outside translators or a shared repository. As with the cache-key bug, the fix seeds the next cycle, because patching one attribute is an invitation to check every sibling attribute immediately.

Candidate Classification

The fastest way to sink a valid report is to overstate it, so I rate a finding by one thing only: the security boundary its runtime proof actually crosses.

That’s why the graphics example earlier was a Medium, not a High. The writes stayed inside memory the page already owned, so nothing crossed an allocation, process, origin, or authority boundary. Both Angular bugs cross a real one: CVE-2026-68945 serves a response across users, and CVE-2026-69151 runs script in the application’s origin. A scanner’s score is only an interpretation of it, but the breached boundary is a fact, so document the boundary and let the rating follow.

Conclusion

The cost of generating a hypothesis, writing a negative control, and checking a patch’s variants has collapsed. What’s scarce now is the discipline to throw the bad ones away quickly and prove the good ones are real.

In practice, that comes down to a few habits: threat-model before you prompt, so every question is anchored to one rule; never report a finding without a negative control and a fixed-version comparison; and run every candidate past a fresh, independent model session whose only job is to disprove it. That session is only a filter, though, and the final sign-off on any finding is always a person’s.

This doesn’t automatically favor defenders. The same tools are a download away for anyone, and patch-diff variant farming rewards whoever moves first after a commit ships. This means the takeaway for anyone shipping code is direct: run these passes on your own patches before you release, because someone outside will run them after you ship.

INSIGHTS | September 29, 2026

AI Red Teaming Techniques for Enterprise AI Security

An enterprise security team reviewing AI red teaming techniques in a modern office environment.

Every major security breakthrough begins the same way: attackers find a new surface before defenders think to look there. It happened with networks, web applications, and the cloud. Now, as organizations embed artificial intelligence into their most critical operations, it is happening with AI systems as well, and conventional security testing was never designed to address it. That gap is exactly what AI red teaming techniques were built to close.

“AI red teaming reveals how attackers interact with AI systems in practice, exposing risks that traditional security testing often misses.” – IOActive Security Team

AI Red Teaming Techniques

Prompt Injection

What it is

A class of attacks where adversaries insert malicious instructions into AI input channels to override system behavior, hijack outputs, or trigger unauthorized actions.

How it works

Direct attacks manipulate user-facing prompts to override system instructions. Indirect attacks embed malicious commands inside content the AI trusts: retrieved documents, browsed webpages, or received emails. This allows attackers to compromise a system without ever interacting with it directly. Red teams use tools such as Garak and PromptBench to generate and score injection payloads across both vectors systematically. A structured engagement first maps every external input source the model trusts, then tests each path with escalating payload complexity to identify where instructions can be overridden.

Expected outcomes and benefits

Testing exposes which input paths, data sources, and integration points carry the highest risk of compromise. Organizations gain a clear map of where instruction override is possible and under what conditions.

Limitations

Injected instructions are difficult to detect because they can closely mimic legitimate input. Full coverage requires testing both direct and indirect vectors, and indirect paths multiply as AI systems access more external data sources.

Best for

Organizations deploying LLMs with access to external data, retrieval-augmented generation pipelines, agentic workflows, or enterprise integrations such as email, document management, and third-party APIs.

Prompt injection is the defining vulnerability class of the AI era. In direct attacks, adversaries manipulate user input to override system instructions. In indirect attacks, malicious instructions are embedded inside content the AI trusts: retrieved documents, browsed webpages, or received emails.

The risk scales with access. AI agents connected to enterprise platforms move 16 times more data than human users, turning a single compromised agent into an organization-wide exposure event, according to Obsidian Security. Indirect attacks now account for over 55% of observed prompt injection incidents, with 20 to 30% higher success rates than direct attacks due to stealth delivery through trusted content. OWASP ranks prompt injection as the number one vulnerability in its 2025 Top 10 for LLM Applications, with 73% of audited production systems showing exposure.

Jailbreak Testing

What it is

Systematic attempts to bypass the safety mechanisms, content filters, and alignment controls built into AI models, exposing gaps between intended behavior and actual behavior under adversarial pressure.

How it works

Red teams probe model guardrails using roleplay scenarios, multi-turn escalation sequences, adversarial rephrasing, cross-language attacks, and varied stylistic prompts designed to shift model behavior beyond its trained constraints.

Tools such as PyRIT (Microsoft’s Python Risk Identification Toolkit for red teamers) automate payload generation and track bypass rates across test runs, distinguishing a structured red team evaluation from ad hoc user experimentation. A formal engagement establishes a behavioral baseline, tests attack categories systematically, and maps each bypass to the specific guardrail or alignment control that failed.

Expected outcomes and benefits

Testing identifies which safety controls hold under pressure and which fail, along with the specific attack patterns most likely to succeed against a given deployment. Organizations can prioritize remediation based on realistic risk, not theoretical exposure.

Limitations

Success rates vary by model version and configuration. Not all bypasses carry equivalent risk, and some remediation options depend on controls that model providers, not operators, must implement.

Best for

Organizations deploying customer-facing LLMs, models with access to sensitive or regulated data, or AI systems where harmful outputs carry legal, reputational, or operational consequences.

Jailbreaks target safety mechanisms, bypassing the content filters and alignment controls built into a model. Roleplay-based attacks achieve 89.6% success rates against large language models. Multi-turn sequences, where an attacker escalates gradually across a conversation, reach 97% success within five exchanges. AI red teams probe these boundaries systematically across diverse attack styles, languages, and escalation strategies.

AI Agent Abuse and Privilege Escalation

What it is

Testing that targets autonomous AI agents’ susceptibility to goal hijacking, tool misuse, and unauthorized privilege escalation across the APIs, databases, and multi-agent environments they operate in.

How it works

Red teams attempt to redirect agent objectives, abuse tool access, and escalate privileges across agent architectures. In multi-agent environments, testers evaluate whether a single injected instruction can propagate across co-running agents in a cascading compromise.

Engagements begin by mapping the agent’s full tool inventory, permission scope, and trust relationships before testing whether crafted inputs can redirect agent behavior toward attacker-controlled objectives. MITRE ATLAS and custom agentic attack playbooks structure the engagement by threat actor objective rather than by system component.

Expected outcomes and benefits

Testing uncovers exploitable flaws in agent tool-execution logic, quantifies cascading risk in multi-agent pipelines, and validates whether permission boundaries hold under adversarial conditions.

Limitations

Scope grows significantly in complex multi-agent deployments. Comprehensive coverage requires deep access to agent architecture, tool configurations, and the external systems agents are authorized to reach.

Best for

Organizations running agentic AI workflows connected to enterprise systems, databases, or APIs, particularly where agents can take autonomous action such as sending emails, executing transactions, or modifying records.

Agentic AI introduces risks with no parallel in traditional testing. Agents plan, take action, and use tools: sending emails, querying databases, calling APIs, and chaining multi-step operations autonomously.

40% of AI agent frameworks contain exploitable prompt injection flaws in their tool-execution logic. Autonomous agents that call external APIs carry up to 2.5 times higher risk exposure than standalone models. In multi-agent environments, a single injected instruction can propagate to 48% of co-running agents in a cascading compromise. Red teams test for goal hijacking, tool misuse, and privilege escalation across these architectures.

Training Data Attacks and RAG Poisoning

What it is

Attacks that manipulate the data an AI system retrieves or learns from, corrupting its outputs and steering its behavior without touching the model itself.

How it works

Adversaries introduce crafted documents into retrieval pipelines or training datasets. Even a small number of poisoned entries can skew AI responses at scale. An adversary who controls what the AI retrieves effectively controls what it recommends and what actions it takes.

Red teams inject crafted documents into the retrieval corpus and query the system iteratively to measure how reliably poisoned content influences model outputs. Testing also covers chunk-level embedding manipulation and retrieval ranking abuse to determine how little adversarial content is required to achieve meaningful response distortion.

Expected outcomes and benefits

Testing reveals vulnerabilities in data ingestion pipelines, exposes how content control translates to output manipulation, and identifies supply chain risk in AI systems that rely on external or user-contributed data.

Limitations

Poisoning effects can be subtle and difficult to detect without targeted testing. Comprehensive assessment requires visibility into retrieval pipelines, document ingestion processes, and embedding logic, which may require close coordination with internal data and engineering teams.

Best for

Organizations using RAG architectures, enterprise knowledge bases, or AI systems trained on internal or third-party data, particularly where retrieved content directly shapes model output or user-facing recommendations.

Retrieval-Augmented Generation systems, which ground model responses in dynamically retrieved content, are vulnerable to data pipeline manipulation. Research published in Information (2026) shows that just five carefully crafted documents can manipulate AI responses 90% of the time through RAG poisoning. As IOActive has documented in its analysis of downstream AI attacks, an adversary who controls what an AI retrieves can control what it says and what it does.

Model Manipulation and Multimodal Attacks

What it is

Attacks targeting model confidentiality and cross-modal vulnerabilities, including efforts to reconstruct proprietary model behavior or embed malicious instructions inside image and audio inputs.

How it works

Model extraction attacks use crafted query sequences to map and replicate model behavior, enabling intellectual property theft or the creation of a shadow model for further exploitation. Multimodal attacks embed adversarial instructions inside images or audio accompanying benign requests, triggering unauthorized actions across input channels.

Extraction testing uses systematic query strategies to probe model decision boundaries and reconstruct behavior patterns without direct model access. Multimodal testing employs tools such as Burp Suite AI extensions and adversarial image generation frameworks to embed instructions inside image or audio payloads, then validates whether the target system processes them as executable commands.

Expected outcomes and benefits

Testing identifies intellectual property exposure, reveals how non-text inputs expand the attack surface, and validates whether input sanitization holds across all supported modalities.

Limitations

Model extraction requires significant query volume to produce a useful reconstruction. Multimodal testing scope depends on which input types the deployment supports, and organizations with restricted API access may face constraints on extraction simulations.

Best for

Organizations with proprietary or fine-tuned models, multimodal AI deployments, or any system that accepts user-submitted images, audio, or document files as part of its core workflow.

Model extraction attacks use crafted queries to reconstruct proprietary model behavior, enabling intellectual property theft or the development of a shadow model for further attacks. As AI systems expand to process images and audio alongside text, adversaries can embed malicious instructions inside images that accompany benign content, triggering unauthorized actions across input channels, according to OWASP’s LLM01:2025 guidance.

The techniques above represent the current front lines of AI adversarial testing. The urgency to apply them is driven by a threat environment that is moving faster than most organizations have adapted.

Why These Threats Are Escalating

The most consequential shift in the AI threat landscape is the rise of autonomous, tool-using agents operating across enterprise environments. A critical vulnerability in Microsoft 365 Copilot (CVE-2025-32711), rated CVSS 9.3, demonstrated how AI command injection in a widely deployed enterprise agent could enable large-scale data theft, as reported by Trend Micro. Controlled security experiments recorded credential theft or system manipulation outcomes in 70% of agent-based prompt injection trials.

OWASP’s December 2025 Top 10 for Agentic Applications and MITRE ATLAS’s October 2025 update, adding 14 new AI-focused techniques, reflect how quickly this space is evolving. The EU AI Act requires adversarial testing for high-risk AI systems ahead of its August 2026 compliance deadline, adding regulatory weight to what was already a security imperative.

The regulatory deadlines and real-world incidents above are not edge cases. They are the baseline risk environment organizations are now operating in, and the financial case for action reflects that reality.

The Business Case for AI Red Teaming

The business case for investing in AI red teaming is grounded in real incidents. 77% of businesses have reported an AI-related security incident. 35% of those incidents were caused by simple prompts, with some resulting in losses exceeding $100,000 per event, according to Adversa AI’s 2025 Security Report via Vectra AI. Organizations that run mature AI red teaming programs report 60% fewer AI-related security incidents than those without.

AI Red Teaming By The Numbers

Organizations are responding by increasingly investing in AI red teaming services. The market was valued at $2.26 billion in 2026 and is projected to reach $6.17 billion by 2030, growing at a 28.5% compound annual growth rate, according to Research and Markets. Demand for AI red teaming is forecasted to surge 35% by 2028, with qualified practitioners already in short supply, according to Practical DevSecOps.

The organizations best positioned to capture that advantage are those that can move beyond generic assessments and apply AI red teaming techniques grounded in real adversary behavior.

The IOActive Approach

IOActive brings decades of adversary simulation expertise to the full spectrum of AI red teaming techniques. The offensive instincts that break into financial institutions and critical infrastructure apply directly to AI systems that reason, decide, and act. IOActive connects proven red team methodology to the emerging AI attack taxonomy, testing how real adversaries would engage with an organization’s models, agents, and data pipelines.

A full engagement covers threat modeling scoped to the organization’s specific AI architecture, prompt injection testing across direct and indirect paths, jailbreak and safety bypass evaluation, agent workflow abuse testing, RAG and training data integrity assessment, privilege escalation validation, and multimodal attack surface review.

The output is a realistic picture of exploitable risk, produced under controlled conditions, with time to remediate before a real adversary finds the same vulnerabilities in production.

The vulnerabilities in your AI systems exist whether or not you have tested for them.

IOActive helps organizations find and fix exploitable risks in large language models, AI agents, and generative systems before adversaries do.

INSIGHTS | September 25, 2026

One Exposure, Many Actors: What the NCSC’s OT Alert Adds to the AA26-097A Picture

Key Takeaways

  • On 27 August 2026, the NCSC published an Alert warning of increased targeting of operational technology (OT) systems across multiple sectors globally, including in the UK, carried out by a range of threat actors and resulting in some limited real-world disruption [1].
  • The Alert is deliberately unattributed. It should not be read as an extension of joint advisory AA26-097A, which attributes a separate and well-documented PLC exploitation campaign to Iranian-affiliated actors [2].
  • Three separate bodies of reporting published between April and August 2026, covering Iranian-affiliated PLC exploitation, Russian FSB Centre 16 router targeting, and unattributed activity against water sector controllers, converge on the same access route of systems reachable directly from the public internet.
  • The FBI and EPA have reported that similarities in network configurations supplied by third parties allowed attackers to repeat successes across multiple victims, making integrator and supplier architecture a first-order concern rather than a downstream one [3].
  • The Alert lands five days before the UK Cyber Security and Resilience Bill reaches Lords Committee Stage on 1 September 2026, placing OT exposure in front of regulators, boards and legislators simultaneously [4].

Why the NCSC’s Alert Matters Now

The NCSC classified its 27 August publication as an Alert rather than guidance. That distinction carries weight. The organisation states that it has been engaging with affected sectors directly in response to recent targeting and is publishing the material to support national resilience efforts, which indicates that the advice follows live incident handling rather than horizon scanning [1].

The substance is uncomfortable for anyone who has treated OT exposure as a solved problem. The NCSC reports increased targeting of OT systems across multiple sectors globally, including in the UK, conducted by a range of threat actors, with some limited real-world disruption already recorded [1]. It also sets out a broader judgement. Against a backdrop of technology-enabled uplifts in offensive capability and increased geopolitical instability, the threat from state use of offensive cyber, including outside of conflict, has almost certainly increased [1].

The timing compounds the message. The Alert arrives within four months of joint advisory AA26-097A, seven weeks after an international advisory on Russian state targeting of network devices, and four weeks after an FBI and EPA announcement describing degraded water operations in at least seven US states [2][3][5]. Regulators are moving in parallel. The Cyber Security and Resilience Bill is scheduled to enter Lords Committee Stage on 1 September 2026, with Royal Assent expected later in the year [4].

What Does the NCSC Alert Actually Say?

The Alert sets out eight actions. Several restate established practice:

  • Build a definitive view of OT architecture including all assets, communications pathways and external connections
  • Replace default credentials and enforce unique administrator accounts with multi-factor authentication where supported
  • Harden the OT boundary and keep gateways, firewalls, routers and remote access appliances within vendor support
  • Segment OT, management and business networks
  • Maintain tested, ransomware-resistant backups of configurations, controller logic and critical engineering data [1]

Two items deserve closer attention because they move beyond network-layer control.

The first concerns device state. The NCSC advises that OT devices be operated in a condition that prevents remote programming during normal operations, ensuring PLCs are not left in PROGRAM or other maintenance modes and that controller logic uses password-based write protection or equivalent mechanisms to prevent unauthorised changes from malicious endpoints [1]. This is a control on the device itself, not on the path to it, and it assumes the network boundary may fail.

The second concerns protocols. The Alert recommends migrating industrial protocols to secure variants where available, naming DNP3 to DNP3-SAv5, CIP to CIP Security, Modbus to Modbus Security, and OPC DA to OPC UA, while removing telnet and SNMP versions 1 and 2 from management use [1]. Where no secure alternative exists, insecure protocols should be confined to isolated network segments.

The Alert also addresses organisations without OT estates, noting a continuing pattern of disruptive activity against internet-exposed systems and edge devices across all sectors, and directing readers to maintain an accurate inventory of internet-facing systems, retire end-of-life equipment and monitor for unexpected configuration changes or outbound connections [1]. It points UK organisations towards the NCSC’s free Early Warning service and frames the Cyber Assessment Framework as the mechanism through which boards should seek assurance [1].

Notably, the Alert names no threat actor.

How Does This Connect to AA26-097A, and Where Does It Not?

This is the point at which analysis most often goes wrong, and the distinction matters more than the similarity.

Advisory AA26-097A, first published on 7 April 2026 and updated on 22 July 2026, attributes an active campaign to Iranian-affiliated APT actors exploiting internet-connected PLCs across US critical infrastructure. The July update broadened the observed manufacturer scope from Rockwell Automation/Allen-Bradley to include Schneider Electric and Siemens controllers, added detection guidance for malicious changes in reusable code modules within Rockwell PLC programs, and brought the Department of the Treasury onto the authoring byline alongside CISA, the FBI, NSA, EPA, the Department of Energy and US Cyber Command’s Cyber National Mission Force [2].

Separately, an international advisory published in July 2026, co-sealed by the NCSC alongside 18 partner agencies from 12 countries, attributes sustained targeting of poorly configured routers to Russian Federal Security Service Centre 16, tracked variously as Berserk Bear, Energetic Bear, Dragonfly, Ghost Blizzard and Static Tundra. That activity centres on internet-wide scanning for devices accepting default or weak SNMP community strings, followed by exfiltration of device configuration files [5].

Separately again, the FBI and EPA issued a public service announcement on 30 July 2026 describing unattributed malicious cyber actors targeting internet-facing Rockwell Automation/Allen-Bradley MicroLogix 1100 and 1400 PLCs. Water and wastewater utilities in at least seven states reported incidents from 27 July 2026 onwards. The actors changed device IP addresses and set passwords, producing loss of view and, in some cases, loss of function. Reported operational effects included loss of pressure and flooding, with the announcement noting that pressure loss in water systems could potentially allow untreated groundwater to seep into pipes [3].

Four publications carry three different attribution states. One names Iranian-affiliated actors, one names a Russian intelligence unit, and two describe activity the authoring agencies have chosen not to attribute. Collapsing these into a single narrative would be an analytical error, and one that regulated operators cannot afford to make in reporting or board briefings.

What survives the separation is the access route. In every case the initial condition is the same, namely a control system, a management interface or an edge device reachable from the public internet and frequently protected by default, weak or absent credentials. The NCSC’s phrasing, that this activity is being carried out by a range of threat actors, is the more useful framing for defenders precisely because it removes the actor from the risk calculation. Exposure is exploitable by whoever finds it first.

Who is Affected by the NCSC’s OT Alert?

CNI operators with field-deployed OT

Any organisation with internet-exposed OT could be affected. The NCSC is explicit that organisations should not assume their OT is inaccessible from the internet without verifying it, since unintended exposure can arise through misconfigurations, legacy connections or unmanaged assets [1]. Water, wastewater and energy operators with geographically distributed sites and cellular field connectivity carry the highest concentration of this risk.

System integrators and managed service providers

The FBI and EPA observed that across several victims, similarities in network setups provided by third parties may give attackers the opportunity to multiply successes where vulnerable configurations recur across a supplier’s customer base [3]. A single integrator’s default deployment pattern becomes a repeatable attack template. This finding maps directly onto the critical supplier designation powers in the Cyber Security and Resilience Bill.

Organisations without OT

The Alert is explicit that the broader pattern of disruptive activity against internet-exposed systems and edge devices affects all sectors [1]. Routers, firewalls, VPN concentrators and remote access appliances present the same fundamental exposure.

Boards and regulated entities across jurisdictions

UK operators face the CAF as the assurance framework of record and the Cyber Security and Resilience Bill as the coming statutory instrument [1][4]. EU operators are working to NIS2. US operators sit within the CISA advisory and directive framework, including binding requirements on end-of-support edge devices [6]. The technical remediation is common across all three, and only the reporting obligations differ.

What Makes This Exposure So Difficult to Eliminate?

The mitigations in the NCSC Alert are not novel, and that is the difficulty. Every one of the eight actions was recognised practice before August 2026. Their repeated publication indicates a gap between recommendation and implementation rather than a gap in knowledge.

Three factors sustain that gap.

Asset visibility remains hard in OT. Exposure is frequently unintended, arising from a commissioning shortcut, a supplier’s remote support link, or a cellular modem installed to solve an operational problem years earlier. An operator can hold an accurate architecture diagram and still be exposed through an asset that diagram never captured.

Integrity attacks defeat availability-focused monitoring. AA26-097A describes actors using legitimate vendor engineering software to alter controller logic and falsify operator displays, and the FBI reported at least one organisation discovering modified PLC project files after noticing ladder logic discrepancies across several sites [2][3]. Where the control room’s picture of the process is itself manipulated, conventional uptime monitoring will report normality.

Remediation carries operational cost. Removing a PLC from direct internet exposure, migrating a protocol, or replacing an end-of-life gateway involves planned downtime in environments where downtime is the primary risk being managed. This is where technical recommendation meets capital planning, and where accountability for the outcome frequently disperses.

How IOActive Can Help

The NCSC’s Alert describes a condition rather than an incident. That condition is assets reachable from the internet that the owner did not know were reachable, protected by credentials the owner did not know were still default. Verifying that condition is an assessment problem before it is a remediation problem, and it spans the OT estate, the edge estate and the third parties with standing access to both.

IOActive has operated in industrial control environments since building the first proof-of-concept worm against the smart grid in 2009 [9], and has helped define standards and best practices including NIST 800-53 and 800-37. The services below map to the specific gaps this Alert exposes.

Full Stack Security Assessments

The Alert’s first action, to build a definitive view of OT architecture and not assume OT is unreachable without verifying it, is precisely the work most assessments stop short of. Our Full Stack assessments examine the whole environment rather than a single layer, covering internet-facing controllers and HMIs, the OT/IT boundary, the cellular modem paths that frequently provide field sites with their only route to the internet, and the firmware and silicon of the devices themselves through penetration testing, reverse engineering, side-channel analysis and fault injection.

Two of the Alert’s actions sit at the device rather than the network layer. Those are confirming controllers are not left in PROGRAM mode, and migrating industrial protocols to secure variants such as DNP3-SAv5, CIP Security, Modbus Security and OPC UA. These are testable conditions, not policy statements, and they are where an assessment either produces evidence or produces reassurance. As we set out in Cyber Attack Trends 2026, the environments organisations depend on most are routinely the ones they monitor least.

Supply Chain Integrity

The FBI and EPA finding that similar third-party network configurations allowed attackers to repeat successes across a supplier’s customer base is the most consequential detail in the current reporting, and the least addressable by any single operator acting alone [3]. It also has a direct precedent in our analysis of the Polish energy sector incident, which documented more than 30 facilities breached through the same pattern of internet-facing VPN portals without MFA, where credential reuse across sites turned one compromised account into a fleet-wide problem.

Our Supply Chain Integrity work assesses the security posture of technology providers and critical third parties, covering firmware, embedded systems, remote access arrangements and procurement processes, so that inherited risk is identified before it becomes a shared incident. For UK operators, this maps onto the critical supplier designation powers in the Cyber Security and Resilience Bill [4].

Red Team and Purple Team Services

The Alert notes that OT environments are typically static and predictable, which makes baseline monitoring highly effective at identifying unauthorised activity [1]. The question is whether a given deployment actually achieves that in practice. Adversarial testing is how an operator finds out before an adversary does, particularly against integrity attacks such as altered controller logic and falsified operator displays, which availability-focused monitoring is not built to catch. Our Purple Team work translates those findings into measurable detection improvements, and we set out the distinction between the two approaches in Red Team vs Penetration Testing.

Advisory Services

The eight actions in this Alert have all been published before, in various forms, and that is the problem worth solving. When we examined the Minnesota water utilities in When the Advisory Arrives First, the gap was not the absence of a warning but the absence of an owner for acting on it.

Our Advisory Services cover programmatic security review, security programme development and management, and Virtual CISO support. They turn an alert into a prioritised remediation plan with named accountability, and produce the evidence boards need for CAF or equivalent regulatory assurance. That work is increasingly shaped by converging regimes across all three jurisdictions, as we examined in our analysis of the UK Energy Sector Cyber Security Strategy and the Five Eyes statement on AI and cyber risk. The latter is directly relevant to the NCSC’s judgement here that technology-enabled uplifts in capability are part of why the threat has increased [1].

If you would like to discuss how your organisation’s internet-facing OT and edge exposure measures up against the activity described in this Alert, we welcome the conversation.

  1. Verify exposure rather than assuming its absence. Build or refresh a definitive view of the OT architecture covering all assets, communications pathways and external connections, and validate it against external scanning results rather than against documentation [1].
  2. Remove control system devices from direct internet reachability. Broker all remote access through a secure gateway or jump host so that OT is never directly exposed to external networks, and secure cellular modems used for field connectivity with strong authentication and logging [1][3].
  3. Eliminate default and shared credentials on OT and edge devices. Enforce unique administrator accounts, enable multi-factor authentication where supported, and use key-based authentication in preference to passwords where the protocol allows [1].
  4. Enforce device-level write protection. Confirm that PLCs are not left in PROGRAM or maintenance modes during normal operations and that controller logic is protected against unauthorised modification [1].
  5. Validate controller logic integrity. Use vendor integrity checking tools to compare running programs against known-good logic, and verify that backups are free of malicious logic before restoration [3].
  6. Retire or isolate end-of-support edge devices. Maintain a rolling replacement forecast reviewed against ownership and procurement, and apply compensating controls with firm decommission dates where replacement is delayed [3][6].
  7. Baseline and monitor OT network traffic. OT environments are typically static and predictable, which makes baseline monitoring effective at identifying communication with PLCs and HMIs from unexpected devices, networks or routes [1].
  8. Rehearse manual operation and recovery. Test the capability to revert to manual control, isolate affected systems and restore from trusted backups, and treat those exercises as evidence for CAF or equivalent regulatory assurance [1][3].

Conclusion

The NCSC’s August Alert does not describe a new technique, a new vulnerability class or a new adversary. It describes a durable condition that a widening set of actors continues to find and exploit, namely control systems and edge devices reachable from the open internet. The value in reading it alongside AA26-097A is not in merging the two, but in observing that campaigns with entirely different sponsors, objectives and levels of sophistication are arriving at the same door.

That has a practical consequence for how operators prioritise. Attribution shapes the diplomatic and sanctions response, but it does not change the remediation. An internet-facing PLC with a default password represents identical risk whether the entity that finds it is a state intelligence service or an opportunistic scanner. As the UK’s statutory regime moves towards Royal Assent and the EU and US frameworks tighten in parallel, the operators best positioned will be those who can evidence what they expose to the internet, and who owns the answer.

References

  1. National Cyber Security Centre, Disruptive cyber activity highlights risk from internet-exposed systems and edge devices, 27 August 2026. https://www.ncsc.gov.uk/news/disruptive-cyber-activity-highlights-risk-from-internet-exposed-systems-and-edge-devices
  2. CISA, FBI, NSA, EPA, DOE, US Cyber Command CNMF and Department of the Treasury, Joint Cybersecurity Advisory AA26-097A, Iranian-Affiliated Cyber Actors Exploit Programmable Logic Controllers Across US Critical Infrastructure, published 7 April 2026, updated 22 July 2026. https://www.cisa.gov/news-events/cybersecurity-advisories/aa26-097a
  3. Federal Bureau of Investigation and Environmental Protection Agency, Malicious Cyber Actors Targeting Water and Wastewater Sector Internet-Facing Programmable Logic Controllers, Causing Operational Disruptions, 30 July 2026. https://www.fbi.gov/investigate/cyber/alerts/2026/malicious-cyber-actors-targeting-water-and-wastewater-sector-internet–facing-programmable-logic-controllers-causing-operational-disruptions
  4. UK Parliament, Cyber Security and Resilience (Network and Information Systems) Bill, HL Bill 32, Lords Second Reading 14 July 2026, Committee Stage 1 September 2026. https://bills.parliament.uk/bills/4035
  5. National Cyber Security Centre, UK and Allies urge critical sectors to improve defences against Russian intelligence targeting, July 2026. https://www.ncsc.gov.uk/news/uk-and-allies-urge-critical-sectors-to-improve-defences-against-russian-intelligence-targeting
  6. CISA, Reducing the Attack Surface for End-of-Support Edge Devices and Binding Operational Directive 26-02. https://www.cisa.gov/resources-tools/resources/reducing-attack-surface-end-support-edge-devices
  7. NCSC-UK, FBI and CISA, Secure Connectivity Principles for Operational Technology. https://www.ncsc.gov.uk/collection/operational-technology/secure-connectivity
  8. National Cyber Security Centre, Cyber Assessment Framework. https://www.ncsc.gov.uk/collection/cyber-assessment-framework
  9. M. Davis, IOActive, Advanced Metering Infrastructure (Smart Grid) Device Security, Black Hat USA 2009. https://blackhat.com/presentations/bh-usa-09/MDAVIS/BHUSA09-Davis-AMI-SLIDES.pdf
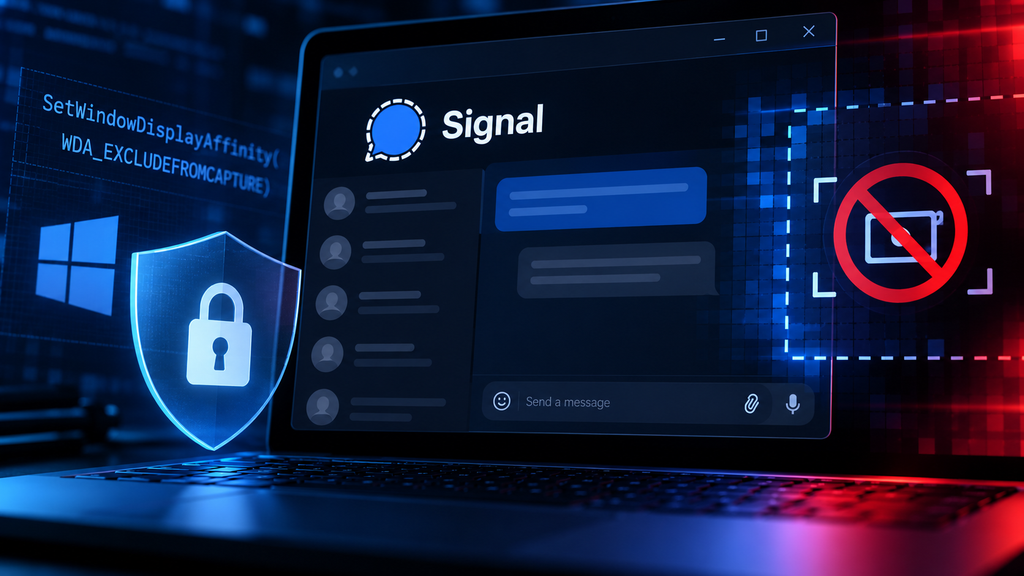
INSIGHTS | September 22, 2026

IT Risk Management Strategies: Key Metrics & Trends

Cyberattacks and data breaches have ranked as the number one global business concern for three consecutive years, according to Aon’s 2025 Global Risk Management Survey. The organizations still managing risk reactively are paying a measurable price. Hyperproof’s 2026 IT Risk and Compliance Benchmark Report found that 50% of those organizations suffered a breach in 2025. Among organizations with integrated, automated programs, the breach rate dropped to 27%.

That 23-point gap reflects a strategic difference in program design: how often risk is assessed, how findings connect to business decisions, and whether testing reflects real-world attack conditions.

This piece identifies key IT risk management strategies that separate mature programs from vulnerable ones, anchored in benchmarks from Verizon, Forrester, IBM, and Hyperproof:

  • Shift from periodic to continuous risk assessment
  • Align security testing to where attackers are actually moving
  • Extend technical validation into third-party and supply chain environments
  • Treat AI red teaming as a separate discipline from traditional red teaming
  • Quantify risk in business terms to improve security investment decisions

IT Risk Management Strategies

StrategyWhat It CatchesWhen to PrioritizeSign of Maturity
1. Shift to continuous risk assessmentBlind spots between assessment cyclesBoard lacks risk visibility; breach rate exceeds benchmarksNIST CSF 2.0 Govern in place; findings escalate to leadership on a defined cadence
2. Align testing to attacker trajectoriesAssessments that miss active threat vectorsEdge devices, ransomware, or third-party vectors are outside current scopeTTPs modeled on current threat actor behavior, not generic categories
3. Extend technical validation into third-party environmentsVendor programs limited to questionnaires and attestationsThird-party access is broad, or a vendor breach occurred in the past 24 monthsCritical suppliers tested under realistic attack conditions
4. Treat AI red teaming as a separate disciplineAI deployments assessed only against traditional controlsLLMs, ML models, AI APIs, or AI-integrated hardware are in productionPrompt injection, data poisoning, and adversarial inputs tested separately from IT infrastructure
5. Quantify risk in business termsSecurity findings that never reach prioritization or budget decisionsSecurity investment lacks ROI framing; findings stay technicalFAIR-based financial exposure tied to findings; risk reported in dollar terms

5 IT Risk Management Strategies That Separate High-Maturity Programs from Vulnerable Ones

“Effective IT risk management strategies prioritize the risks most likely to disrupt critical business operations, not simply the risks that are easiest to identify.” —IOActive

Strategy 1: Shift from Periodic to Continuous Risk Assessment

The biggest differentiator between high-maturity and low-maturity programs is not which framework they use. It is how often they assess.

Treating risk assessment as a periodic compliance exercise creates blind spots between cycles. The 23-point breach rate differential between reactive and integrated programs reflects this directly. Forrester’s State of Enterprise Risk Management 2025 adds another dimension: organizations without board-level ERM visibility were 20% more likely to suffer six or more critical risk events in a given year.

For most enterprise security programs, “continuous” does not mean auditing everything at once. It means layering assessment activities across defined cadences:

  • Ongoing: Automated monitoring of critical assets, threat intelligence feeds, and anomaly detection across production environments
  • Quarterly: Risk register review, third-party posture updates, and findings-to-remediation tracking against defined SLAs
  • Annually (minimum): Full penetration test of the environment, including edge devices and third-party access points
  • Change-triggered: Targeted assessment after any significant infrastructure change, acquisition, new vendor integration, or disclosed supplier breach

Two frameworks structure this cadence in practice. NIST CSF 2.0’s Govern function formalizes how risk oversight connects to organizational decision-making, not just technical operations. The FAIR (Factor Analysis of Information Risk) methodology translates those findings into probabilistic financial exposure that boards can act on. If current assessments cannot convert a technical finding into a quantified business risk, the reporting structure, not just the testing methodology, needs to change. IOActive’s penetration testing and advisory engagements are designed to generate findings at that level of specificity.

Reactive vs. Integrated Risk Programs: How Maturity Drives Breach Outcomes

Program CharacteristicReactive ProgramIntegrated Program
Assessment frequencyAnnual or periodicContinuous, change-triggered
Risk reportingSiloed, technicalTied to business outcomes
Board visibilityLimited or absentFormal ERM governance
Breach rate (2025)50%27%
Framework alignmentAd hocNIST CSF 2.0, FAIR, or equivalent

The table above makes the gap concrete: the difference between a 50% and a 27% breach rate is not a technology gap. It is a program design gap. Every row represents a decision a security leader can change without replacing existing tooling. To close that gap, start with three diagnostics:

  • Audit your assessment cadence. If the last full assessment was more than 12 months ago and was not triggered by an infrastructure change, your program is operating reactively regardless of which framework it claims to follow.
  • Test your reporting chain. Pull the most recent security finding delivered to leadership. If it was framed in technical terms without a financial exposure estimate, the board cannot act on it — and the Forrester data suggests that this gap is directly linked to higher rates of critical risk events.
  • Check framework alignment. NIST CSF 2.0 and FAIR are not aspirational targets. They are the operational baseline of integrated programs. If neither is in use, the program lacks a structured escalation path from findings to resource allocation.

Strategy 2: Align Security Testing to Where Attackers Are Moving

According to the Verizon 2025 DBIR, three vectors account for the most significant attacker movement in 2025: edge devices (exploitation up nearly eightfold), ransomware (up 37% year-over-year in breach data), and third-party environments (now involved in nearly 30% of all breaches, double the prior year). These are not random fluctuations. They reflect a deliberate shift toward the parts of enterprise environments that are hardest to monitor and least likely to be included in standard assessment scopes.

Organizations that limit testing to familiar, well-controlled internal environments are building a risk picture that excludes exactly the vectors attackers are actively exploiting. Effective IT risk management strategies account for where threats are moving: assessments must be built on current threat intelligence and on documented tactics, techniques, and procedures (TTPs) from active threat actors, rather than generic attack categories.

Active Threat Vectors Every IT Risk Management Strategy Must Account For (2025)

Threat Vector2025 TrendAssessment Implication
Ransomware37% YoY in breach dataTest detection and containment, not just prevention
Edge device exploitationNearly 8x growthExpand scope beyond the traditional network perimeter
Third-party involvementDoubled; ~30% of all breachesInclude supplier environments in testing scope
Phishing/social engineeringConsistent top initial access vectorTest employee response under realistic conditions

Strategy 3: Extend Technical Validation Into Third-Party and Supply Chain Environments

Third-party risk has moved from a compliance checkbox to a primary breach vector. Ethixbase360 reported that nearly 30% of all data breaches in 2025 involved third-party vendors or suppliers, double the rate from 2024. When a breach originates from a third-party environment, average remediation costs reach $4.8 million.

Exposure increases as the attack surface expands. SaaS integrations, AI APIs, cloud-managed services, and hardware supply chains create entry points outside an organization’s direct control. Attackers increasingly target upstream suppliers as indirect entry routes into better-defended downstream targets, a vector that questionnaires and attestations alone do not address.

For security leaders ready to move beyond attestation-based programs, four steps define where to start:

  • Classify vendors by access level. Identify which third parties have privileged access to your network, data, or production systems. Those with the highest access represent the highest residual risk if their environments are unvalidated.
  • Audit your current validation method per vendor. For each critical supplier, determine whether your current risk assessment is based on a questionnaire, a certification review, or actual technical testing. Questionnaire-only programs cannot detect active vulnerabilities or misconfigurations in a vendor’s environment.
  • Prioritize vendors who have changed or expanded access in the past 12 months. New SaaS integrations, API connections, and cloud-managed service agreements are the most common sources of unvalidated exposure in enterprise supply chains.
  • Schedule technical testing of your highest-risk suppliers. This means penetration testing of vendor-facing access points and, where applicable, hardware and firmware assessment for vendors operating in your physical or OT environment.

Technical validation of critical supplier environments, tested under realistic attack conditions, is where the real picture emerges. IOActive’s Supply Chain Integrity services take an attacker’s-mindset approach across every technology layer, including hardware, firmware, and silicon-level components.

Strategy 4: Treat AI Red Teaming as a Separate Discipline from Traditional Red Teaming

AI is both a security tool and a security risk vector, and those two realities require separate responses. IOActive’s AI Security Services address the risk side: testing the AI implementations that enterprise clients are deploying for vulnerabilities that traditional security assessments were not built to find. The distinction is not a matter of degree; it is a difference in target, methodology, threat framework, and deliverable.

AI Red Teaming vs. Traditional Red Teaming: Two Disciplines, Two Different Attack Surfaces

DimensionTraditional Red TeamAI Red Team
Primary targetNetworks, endpoints, applications, physical controlsML models, LLMs, training pipelines, AI APIs
Key attack typesLateral movement, privilege escalation, social engineeringPrompt injection, model extraction, data poisoning, adversarial inputs
Threat frameworkMITRE ATT&CK (Enterprise, Mobile, ICS)MITRE ATLAS, OWASP LLM Top 10
ScopeIT perimeter, cloud infrastructure, physical accessInference endpoints, training data, AI-integrated hardware, CI/CD pipelines
Deliverable focusControl gaps, detection capability, IR readinessModel robustness, data integrity, AI compliance posture
On-prem applicabilityYesPartial (AI-integrated hardware and embedded systems)

The Adversa AI 2025 report found that 35% of real-world AI security incidents resulted from simple prompt attacks, with no specialized tooling required: only manipulated inputs causing unintended behavior or data leakage. That finding aligns with IOActive’s own research, which evaluated 27 leading AI models using 730 real-world programming prompts across 27 languages and 219 vulnerability categories. Organizations testing AI implementations only against traditional security controls are not testing against the attacks that are actually succeeding in the field.

For security leaders building an AI red teaming capability or evaluating whether one is needed, four steps define where to start:

  • Inventory every AI deployment in production. Include LLMs, ML models, AI-integrated APIs, and any hardware with embedded AI components. Systems that have not been formally cataloged cannot be scoped into a testing program.
  • Determine how each has been tested to date. If AI systems have only been assessed under a traditional penetration testing scope, prompt injection, data poisoning, and adversarial input attacks have not been evaluated. That gap is where 35% of real-world AI incidents originate.
  • Prioritize by exposure. Public-facing AI interfaces and AI systems with access to sensitive data or internal decision-making pipelines carry the highest risk and should be tested first under MITRE ATLAS and OWASP LLM Top 10 frameworks.
  • Engage an AI red team, not a traditional one. The methodologies, tooling, and threat frameworks are different enough that assigning AI security testing to a conventional red team produces incomplete findings. The attack surface requires a purpose-built discipline.

Strategy 5: Quantify Risk in Business Terms to Improve Security Investment Decisions

Investment without measurement does not close the breach rate gap. Hyperproof found that 58% of GRC professionals anticipated increased risk and compliance spending in 2026, and that trajectory is expected to continue. The organizations extracting the most value from that spend are those directing it toward real-world validation with measurable business-risk outputs.

The FAIR methodology converts technical findings, such as a misconfigured edge device or an unpatched vendor API, into probabilistic estimates of financial exposure. NIST CSF 2.0’s Govern function formalizes the escalation path, providing a structure for how those estimates reach board-level decision-makers and translate into resource allocation. The result is a feedback loop: assessments generate findings, findings translate into financial exposure, and financial exposure directs investment where actual risk is highest.

Find Out Where Your IT Risk Management Strategies Actually Stand

Before directing more investment toward security tools or programs, three questions can identify where current gaps are largest:

  1. Can your team articulate, with data, how a sophisticated threat actor would move through your environment today? If the most recent assessment was conducted more than 12 months ago or did not include edge devices and third-party access points, the answer is likely no.
  2. Have your AI implementations been tested against prompt injection, data poisoning, and adversarial inputs? Testing AI only against traditional security controls leaves the most common AI-specific attack vectors unaddressed.
  3. Does your third-party risk program include technical validation of critical supplier environments, or only attestations and questionnaires? Given that 30% of 2025 breaches involved third parties, questionnaire-only programs leave a primary breach vector unvalidated.

If those questions cannot be answered with confidence, they are the gaps worth closing first. IOActive’s research-driven assessments connect offensive security findings to the business risk decisions that CISOs, CIOs, and boards need to build mature IT risk management strategies.

Sources

  1. Aon 2025 Global Risk Management Survey
  2. Forrester Business Risk Survey, 2025
  3. Forrester: The State of Enterprise Risk Management, 2025
  4. Hyperproof 2026 IT Risk and Compliance Benchmark Report
  5. Verizon 2025 Data Breach Investigations Report (DBIR)
  6. IBM/Ponemon Cost of a Data Breach 2025 (via CompTIA State of Cybersecurity 2025)
  7. Ethixbase360: Top 10 Third-Party Cyber Breaches of 2025
  8. FortifyData: Third-Party Data Breaches in 2025
  9. Adversa AI 2025 Report
  10. Grand View Research: Risk Management Market Report
  11. IOActive Resources: AI Model Research (730 prompts, 27 languages, 219 vulnerability categories)
  12. NIST Cybersecurity Framework (CSF) 2.0