01
Demonstrate
We prove exploitability instead of listing possibilities.

We simulate like an attacker and report like an engineer.
of AI-generated code samples were fully exploitable when we tested 27 AI models and coding tools.
Read the research ->Cybersecurity research and AI model diagnostics.
RAG and tool calling turn one request into calls against files, APIs and production systems. Select a hop to see how attackers use it, and how we test it.
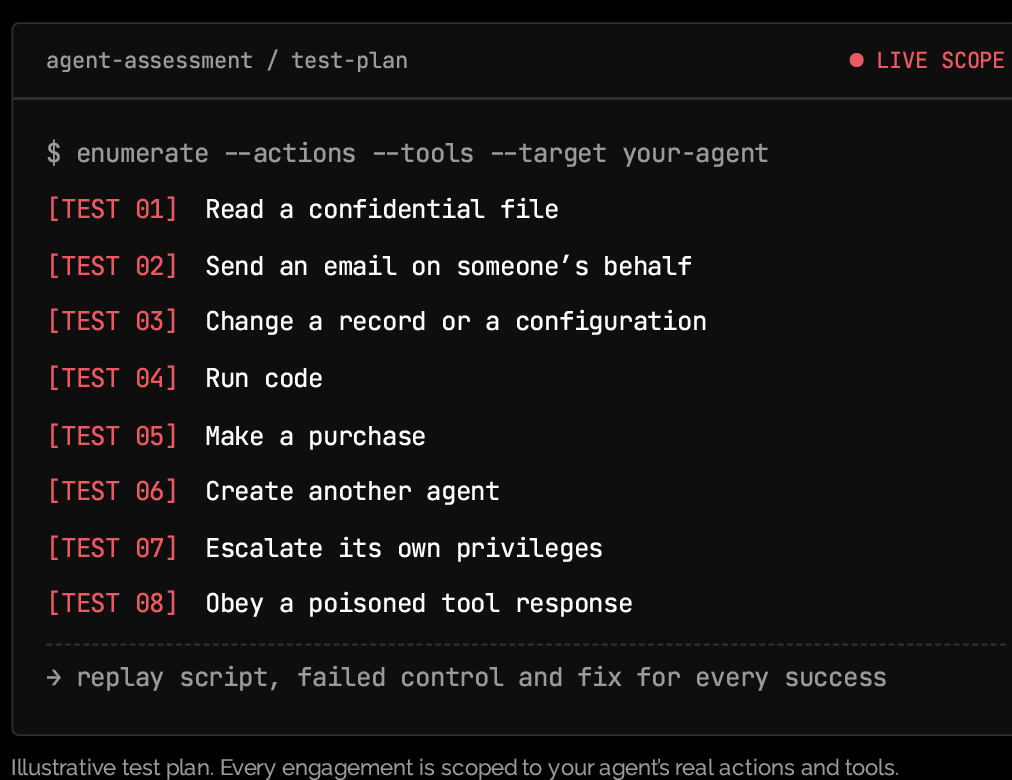
An agent can send email, change records and run code. We try to make it do every one of those things for us, including through another agent or a poisoned tool response. For each success, we show you which control failed and recommend the fix there.
Fourteen engagements that follow the life of an AI system. Start wherever you are.
We prove exploitability instead of listing possibilities.
Results are checked across seeds and decoding settings to separate durable failures from noise.
Every issue ships with the inputs and replay steps that reproduce it, and a named owner for the fix.
After you fix, we rerun the same harness and measure the change in attack success.
730 prompts, 27 models and tools. Nearly a third of samples fully exploitable.
Read the study ->Published with Alais Robotics.
Read more ->How an IOActive consultant usedAI-generated voices against a livetarget.
Read more ->Findings demonstrated with evidence you can replay, fixes assigned to a named owner, and a retest once you’ve fixed them.