Entropy
1. http://en.wikipedia.org/wiki/Entropy_%28information_theory%29
https://fbcdn-sphotos-a.akamaihd.net/hphotos-ak-ash4/398297_10140657048323225_750784224_11609676_1712639207_n.jpg
Entropy
1. http://en.wikipedia.org/wiki/Entropy_%28information_theory%29
https://fbcdn-sphotos-a.akamaihd.net/hphotos-ak-ash4/398297_10140657048323225_750784224_11609676_1712639207_n.jpg
A while ago, yours truly gave two talks on SSL traffic analysis: one at 44Con and one at RuxCon. A demonstration of the tool was also given at last year’s BlackHat Arsenal by two of my co-workers. The presented research and tool may not have been as groundbreaking as some of the other talks at those conferences, but attendees seemed to like it, so I figured it might make some good blog content.
Traffic analysis is definitely not a new field, neither in general nor when applied to SSL; a lot of great work has been done by reputable research outlets, such as Microsoft Research with researchers like George Danezis. What recent traffic analysis research has tried to show is that there are enormous amounts of useful information to be obtained by an attacker who can monitor the encrypted communication stream.
A great example of this can be found in the paper with the slightly cheesy title Side-Channel Leaks in Web Applications: a Reality Today, a Challenge Tomorrow. The paper discusses some approaches to traffic analysis on SSL-encrypted web applications and applies them to real-world systems. One of the approaches enables an attacker to build a database that contains traffic patterns of the AutoComplete function in drop-down form fields (like Google’s Auto Complete). Another great example is the ability to—for a specific type of stock management web application—reconstruct pie charts in a couple of days and figure out the contents of someone’s stock portfolio.
After discussing these attack types with some of our customers, I noticed that most of them seemed to have some difficulty grasping the potential impact of traffic analysis on their web applications. The research papers I referred them to are quite dry and they’re also written in dense, scientific language that does nothing to ease understanding. So, I decided to just throw some of my dedicated research time out there and come up with a proof of concept tool using a web application that everyone knows and understands: Google Maps.
Since ignorance is bliss, I decided to just jump in and try to build something without even running the numbers on whether it would make any sense to try. I started by running Firefox and Firebug in an effort to make sense of all the JavaScript voodoo going on there. I quickly figured out that Google Maps works by using a grid system in which PNG images (referred to as tiles) are laid out. Latitude and longitude coordinates are converted to x and y values depending on the selected zoom level; this gives a three dimensional coordinate system in which each separate (x, y, z)-triplet represents two PNG images. The first image is called the overlay image and contains the town, river, highway names and so forth; the second image contains the actual satellite data.
Once I had this figured out the approach became simple: scrape a lot of satellite tiles and build a database of the image sizes using the tool GMapCatcher. I then built a tool that uses libpcap to approximate the image sizes by monitoring the SSL encrypted traffic on the wire. The tool tries to match the image sizes to the recorded (x,y,z)-triplets in the database and then tries to cluster the results into a specific region. This is notoriously difficult to do since one gets so many false positives if the database is big enough. Add to this the fact that it is next to impossible to scrape the entire Google Maps database since, first, they will ban you for generating so much traffic and, second, you will have to store many petabytes of image data.
With a little bit of cheating—I used a large browser screen so I would have more data to work with—I managed to make the movie Proof of Concept – SSL Traffic Analysis of Google Maps.
As shown in the movie, the tool has a database that contains city profiles including Paris, Berlin, Amsterdam, Brussels, and Geneva. The tool runs on the right and on the left is the browser accessing Google Maps over SSL. In the first attempt, I load the city of Paris and zoom in a couple of times. On the second attempt I navigate to Berlin and zoom in a few times. On both occasions the tool manages to correctly guess the locations that the browser is accessing.
Please note that it is a shoddy proof of concept, but it shows the concept of SSL traffic analysis pretty well. It also might be easier to understand for less technically inclined people, as in “An attacker can still figure out what you’re looking at on Google Maps” (with the addendum that it’s never going to be a 100% perfect and that my shoddy proof of concept has lots of room for improvement).
For more specific details on this please refer to the IOActive white paper Traffic Analysis on Google Maps with GMaps-Trafficker or send me a tweet at @santaragolabs.
Firmware analysis is a fascinating area within the vast world of reverse engineering, although not very extended. Sometimes you end up in an impasse until noticing a minor (or major) detail you initially overlooked. That’s why sharing methods and findings is a great way to advance into this field.
There are a few things here worth mentioning:
Some months ago at Black Hat USA 2011 I presented this interesting issue in the workshop “Easy and Quick Vulnerability Hunting in Windows,” and now I’m sharing it with all people a more detailed explanation in this blog post.
C:WindowsInstaller there are many installer files (from already installed applications) with what appear to be random names. When run, some of these installer files (like Microsoft Office Publisher MUI (English) 2007) will automatically elevate privileges and try to install when any Windows user executes them. Since the applications are already installed, there’s no problem, at least in theory.
C:UsersusernameAppDataLocalTemp, which is the temporary folder for the current user. The created file is named Hx????.tmp (where ???? seem to be random hex numbers), and it seems to be a COM DLL from Microsoft Help Data Services Module, in which its original name is HXDS.dll. This DLL is later loaded by msiexec.exe process running under the System account that is launched by the Windows installer service during the installation process.
msiexec.exe process generates an MD5 hash of the DLL file and compares it with a known-good MD5 hash value that is read from a file located in C:WindowsInstaller, which is only readable and writable by System and Administrators accounts.
C:windowstemp folder, possibly allowing the same attack.
char string version, respectively. If you’ve done any development on Windows systems, you’ll definitely be no stranger to wide character strings.
int) from the packet and performs a bounds check. If the check passes, a string of the specified length (assumed to be a UTF-16 string) is copied from the packet buffer to a fresh wide char array on heap.
[ … ]
if(packet->dataLen > 34 || packet->dataLen < sizeof(wchar_t)) bailout_and_exit();
size_t bufLen = packet->dataLen / sizeof(wchar_t);
wchar_t *appData = new wchar_t[bufLen];
memcpy(appData, packet->payload, packet->dataLen);
[ … ]
char array. But consider what would happen if packet->dataLen was an odd number. For example, if packet->dataLen = 11, we end up with size_t bufLen = 11 / 2 = 5 since the remainder of the division will be discarded.
memcpy() copies 11 bytes. Since five wide chars on Windows is 10 bytes (and 11 bytes are copied), we have an off-by-one overflow. To avoid this, the modulo operator should be used to check that packet->dataLen is even to begin with; that is:
if(packet->dataLen % 2) bailout()
len + 1 is used instead of the len + 2 that is required to account for the extra NULL byte(s) needed to terminate wide char arrays, for example:
int alloc_len = len + 1;
wchar_t *buf = (wchar_t *)malloc(alloc_len);
memset(buf, 0x00, len);
wcsncpy(buf, srcBuf, len);
srcBuf had len wide chars in it, all of these would be copied into buf, but wcsncpy() would not NULL terminatebuf. With normal character arrays, the added byte (which will be a NULL because of the memset) would be the NULL terminator and everything would be fine. But since wide char strings need either a two- or four-byte NULL terminator (Windows and UNIX, respectively), we now have a non-terminated string that could cause problems later on.
int destLen = (stringLen * (sizeof(wchar_t)) + sizeof(wchar_t);
wchar_t *destBuf = (wchar_t *)malloc(destLen);
MultiByteToWideChar(CP_UTF8, 0, srcBuf, stringLen, destBuf, destLen);
[ do something ]
MultiByteToWide API is documented at <http://msdn.microsoft.com/en-us/library/windows/desktop/dd319072%28v=vs.85%29.aspx>.
MultiByteToWideChar is the length of the destination buffer in wide characters, not in bytes, as the call above was done. Our destination length is out by a factor of two here (or four on UNIX-like systems, generally) and ultimately we can end up overrunning the buffer. These sorts of mistakes result in overflows and they’re surprisingly common.
char string functions, like wcsncpy(), for example:unsigned int destLen = (stringLen * sizeof(wchar_t)) + sizeof(wchar_t);
wchar_t destBuf[destLen];
memset(destBuf, 0x00, destLen);
wcsncpy(destBuf, srcBuf, sizeof(destBuf));
sizeof(destuff) for maximum destination size would be fine if we were dealing with normal characters, this doesn’t work for wide character buffers. Instead, sizeof(destBuf) will return the number of bytes indestBuf, which means the wcsncpy() call above it can end up copying twice as many bytes to destBuf as intended—again, an overflow.
char equivalent string manipulation functions are also prone to misuse in the same ways as their normal char counterparts—look for all the wide char equivalents when auditing such functions as swprintf,wcscpy, wcsncpy, etc. There also are a few wide char-specific APIs that are easily misused; take, for example,wcstombs(), which converts a wide char string to a multi-byte string. The prototype looks like this:size_t wcstombs(char *restrict s, const wchar_t *restrict pwcs, size_t n);
n bytes have been written to s or when a NULL terminator is encountered in pwcs (the source buffer). If an error occurs, i.e. a wide char in pwcs can’t be converted, the conversion stops and the function returns (size_t)-1, else the number of bytes written is returned. The MSDN considerswcstombs() to be deprecated, but there are still a few common ways to mess when using it, and they all revolve around not checking return values.
int i;
i = wcstombs( … ) // wcstombs() can return -1
buf[i] = L'';
n, the destination buffer won’t be NULL terminated, so any string operations later carried out on or using the destination buffer could run past the end of the buffer. Two possible consequences are a potential page fault if an operation runs off the end of a page or potential memory corruption bugs, depending on howdestbuf is usedlater . Developers should avoid wcstombs() and use wcstombs_s() or another, safer alternative. Bottom line: always read the docs before using a new function since APIs don’t always do what you’d expect (or want) them to do.
char and normal char functions. A good example would be incorrectly using strlen() on a wide character string instead of wcslen()—since wchar strings are chock full of NULL bytes, strlen() isn’t going to return the length you were after. It’s easy to see how this can end up causing security problems if a memory allocation is done based on a strlen() that was incorrectly performed on a wide char array.
wchars. In the examples above, I have assumed sizeof(wchar_t) = 2; however, as I’ve said a few times, this is NOT necessarily the case at all, since many UNIX-like systems have sizeof(wchar_t) = 4.
wchar_t *destBuf = (wchar_t *)malloc(32 * 2 + 2);
wcsncpy(destBuf, srcBuf, 32);
destBuff for 32 wide chars + NULL terminator (66 bytes). But as soon as you run this on a Linux box—where wide chars are four bytes—you’re going to get wcsncpy()writing 4 * 32 + 2 = 130 bytes and resulting in a pretty obvious overflow.
sizeof(wchar_t) to find out.
char functions, and ensure the math is right when allocating and copying memory. Make sure you check your return values properly and, most obviously, read the docs to make absolutely sure you’re not making any mistakes or missing something important.
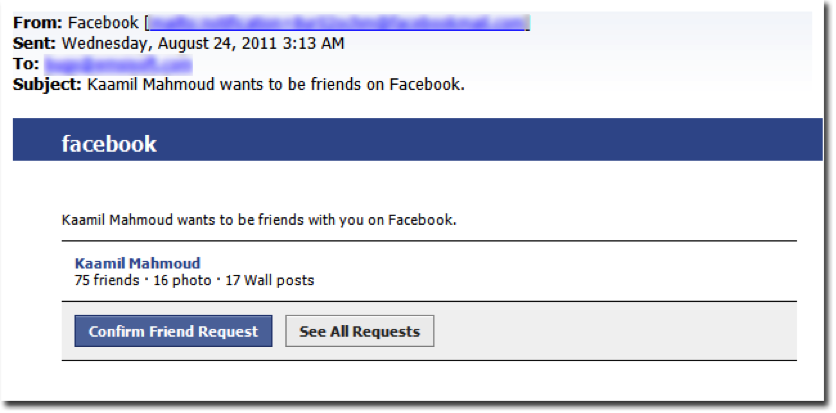
Needs or Likes Templates:
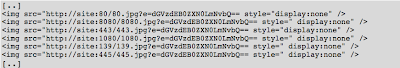
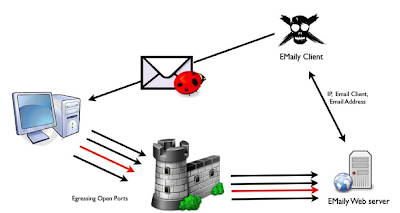
Once we have a target list (emails, names, etc.) and a ruse, we need to begin gathering information about the internal network and infrastructure from within. One possible way of doing this is by sending one or more rounds of emails using specially crafted html templates consisting of several image tags pointing to different ports, as it is shown on the figure below.

Once we have a list of ports we want to scan from an internal perspective, we do not need to generate the entire list. EMaily will automatically generate the list and populated with the corresponding email using the template system as it is shown on the following code snippet, by simply using the %%payload[port 1, … ,port n]%%
You may ask, “but what is to gain from generating this random set of images?” The short answer is lots of information. We will not only be able to confirm that the firewall in the company we are trying to attack is not properly filtering the particular port, but also whenever an application makes an HTTP request, it sends lots of useful information back to the attacker.

This is part three of a four-part social engineering post. The next and final entry will discuss compromising machines.
|
Search Engines
– Google
– Bing
– Yahoo
– AltaVista
|
Social Engines
– LinkedIn
– Google Profiles
– Naymz
– Classmates
– Spoke
– Google+
|
Other Engines
– PGP servers
– Usenets
– GoogleGroups Search
– Spider
– LDAP
|
|
PDF
DOC
DOCX
|
ODP
ODS
ODB
|
XLSX
PPTX
TXT
|
ODT
ASN
|
esearchy.
esearchy CLI command and/or by creating custom scripts using the ESearchy library—that is, they requireesearchy.
help command in the ESearchy tool itself, which is:esearchy –h
since the original conceptualization of computer security, and perhaps even before, social engineering has been in existence. One could say that social engineering began when societies began, whether it was realized or not. It is now time to give some of this work to scripts and applications to make it a little more interesting…
As the years passed in the computer security community, network penetration became more and more necessary, but computers were not the only thing getting compromised. Social engineering was part of the hacker subculture, but it was never a service offered by companies.
In recent years—largely due to the fact that they are doing more business online—companies have become more security aware and networks have become more “secure.” Finding remote vulnerabilities on Internet-facing networks that can be exploited is becoming more and more difficult due, in part, to such realities as the increased safety of operating systems, the standardization of automated patching, and the hiring of security personnel. Having said that, many would argue, “What about corporate networks? Do companies secure their networks the same way they secure production servers?”
The short answer, in my experience, is no. Companies have different approaches to and views about internal and external networks: they often don’t think about internal threats. They fail to understand that internal threats don’t necessarily mean an internal employee going rogue; it could easily be an attacker with access to the corporate network who is attacking it from an internal perspective.
For thousands of reasons and excuses, workstations and internal servers are never kept as secure as external servers: they usually lack up-to-date patching schedules, and are loosely and improperly configured. On top of this already insecure network are the human users, which includes IT admins, engineers, and developers. Your employees.
Employees: A group of people who can perform amazing tasks such as infect their computer in less than two hours, install buggy freeware apps, and open all those links that come with explicit warnings such as DO NOT OPEN – VIRUS FOUND.
To make a story short, hackers, spammers, botnets, criminal organizations, and all the other “bad guys” constantly take advantage of the weakest link in all types of security: The Human Factor, or human stupidity. The reality is, it doesn’t matter how much you harden a computer, you can rely on a human to find a way to compromise that computer.
Social engineers are acutely aware of how human psychology operates, and they are well aware of human needs and feelings. Consequently, they will use and abuse these “issues” to craft their ruses and attacks.
Additionally, due to the rise of social networks in personal and corporate environments, people are constantly checking their Facebook, LinkedIn, email, Twitter, Google+, and Gmail—everyone wants to know what is going on within their company. The 21st century human has an addictive need to be informed in real-time. It is human nature to communicate and interact with people, and to be as informed as you can about your environment. Deep down, we all love to gossip.
Before we even start, it’s worth noting that client-side attacks, phishing attacks, social engineering attacks, and social engineering penetration tests have existed for a long time. Due to the ever-tightening security around networking in recent years on one hand, and the expansion and rapid growth of social networks on the other, these attacks have gained strength, and new attack types are appearing daily, abusing the communication channels humans are working so hard to create.
Standard attack types:
• Classic email-driven social engineering attacks
• Website phishing attacks
• Targeted social hacking (Facebook, LinkedIn, Google+, et cetera)
• Physical social engineering
In my next three posts, I will be walking through the steps to perform a social engineering attack from a corporate point of view as a security consultant. I’ll begin with information gathering, the indispensible “homework phase” that every social engineering engagement should begin with.
I’m glad to start this new blog for IOA Labs by publishing the video demonstrations and updated slides of my Black Hat USA 2011 workshop. I hope you like it, please send me your feedback, questions, etc. We will continue posting cool materials from our researchers very soon, keep tuned!